| Citation: | Jin Z H,Chen K,Tang D B,et al. Visual language model based on improved Transformer[J]. Journal of Beijing University of Aeronautics and Astronautics,2026,52(11):4019-4028 (in Chinese)

|
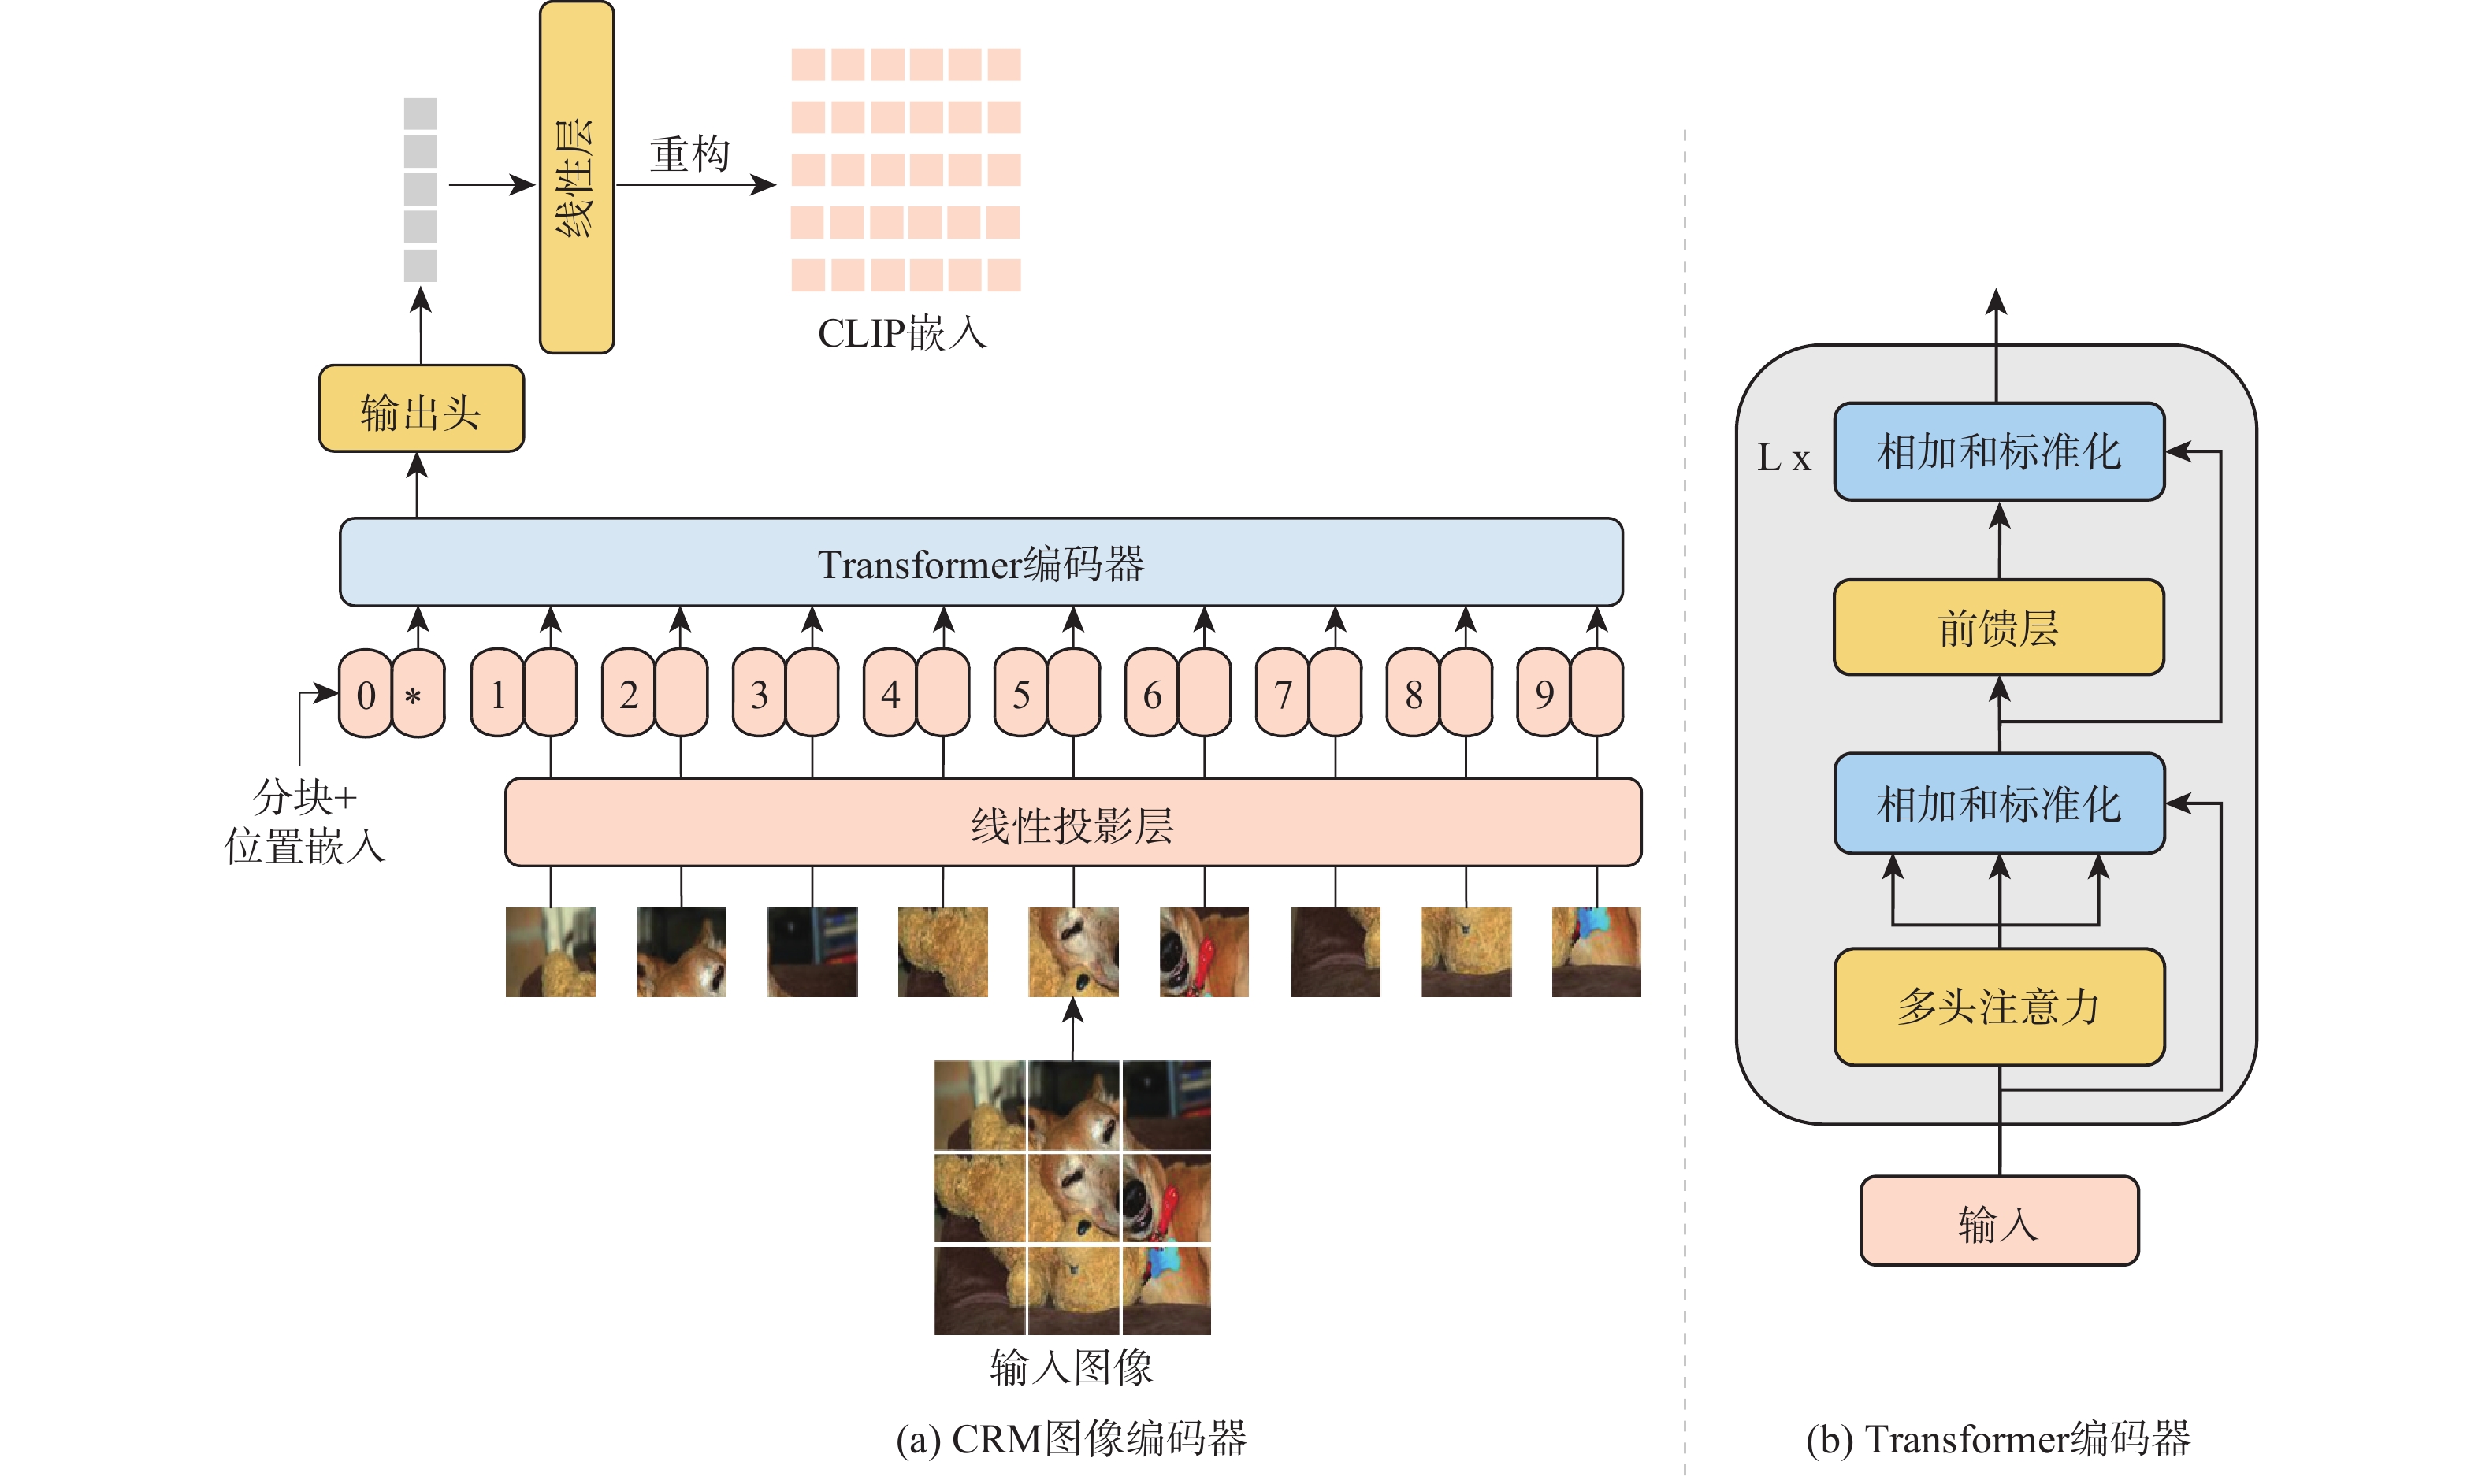
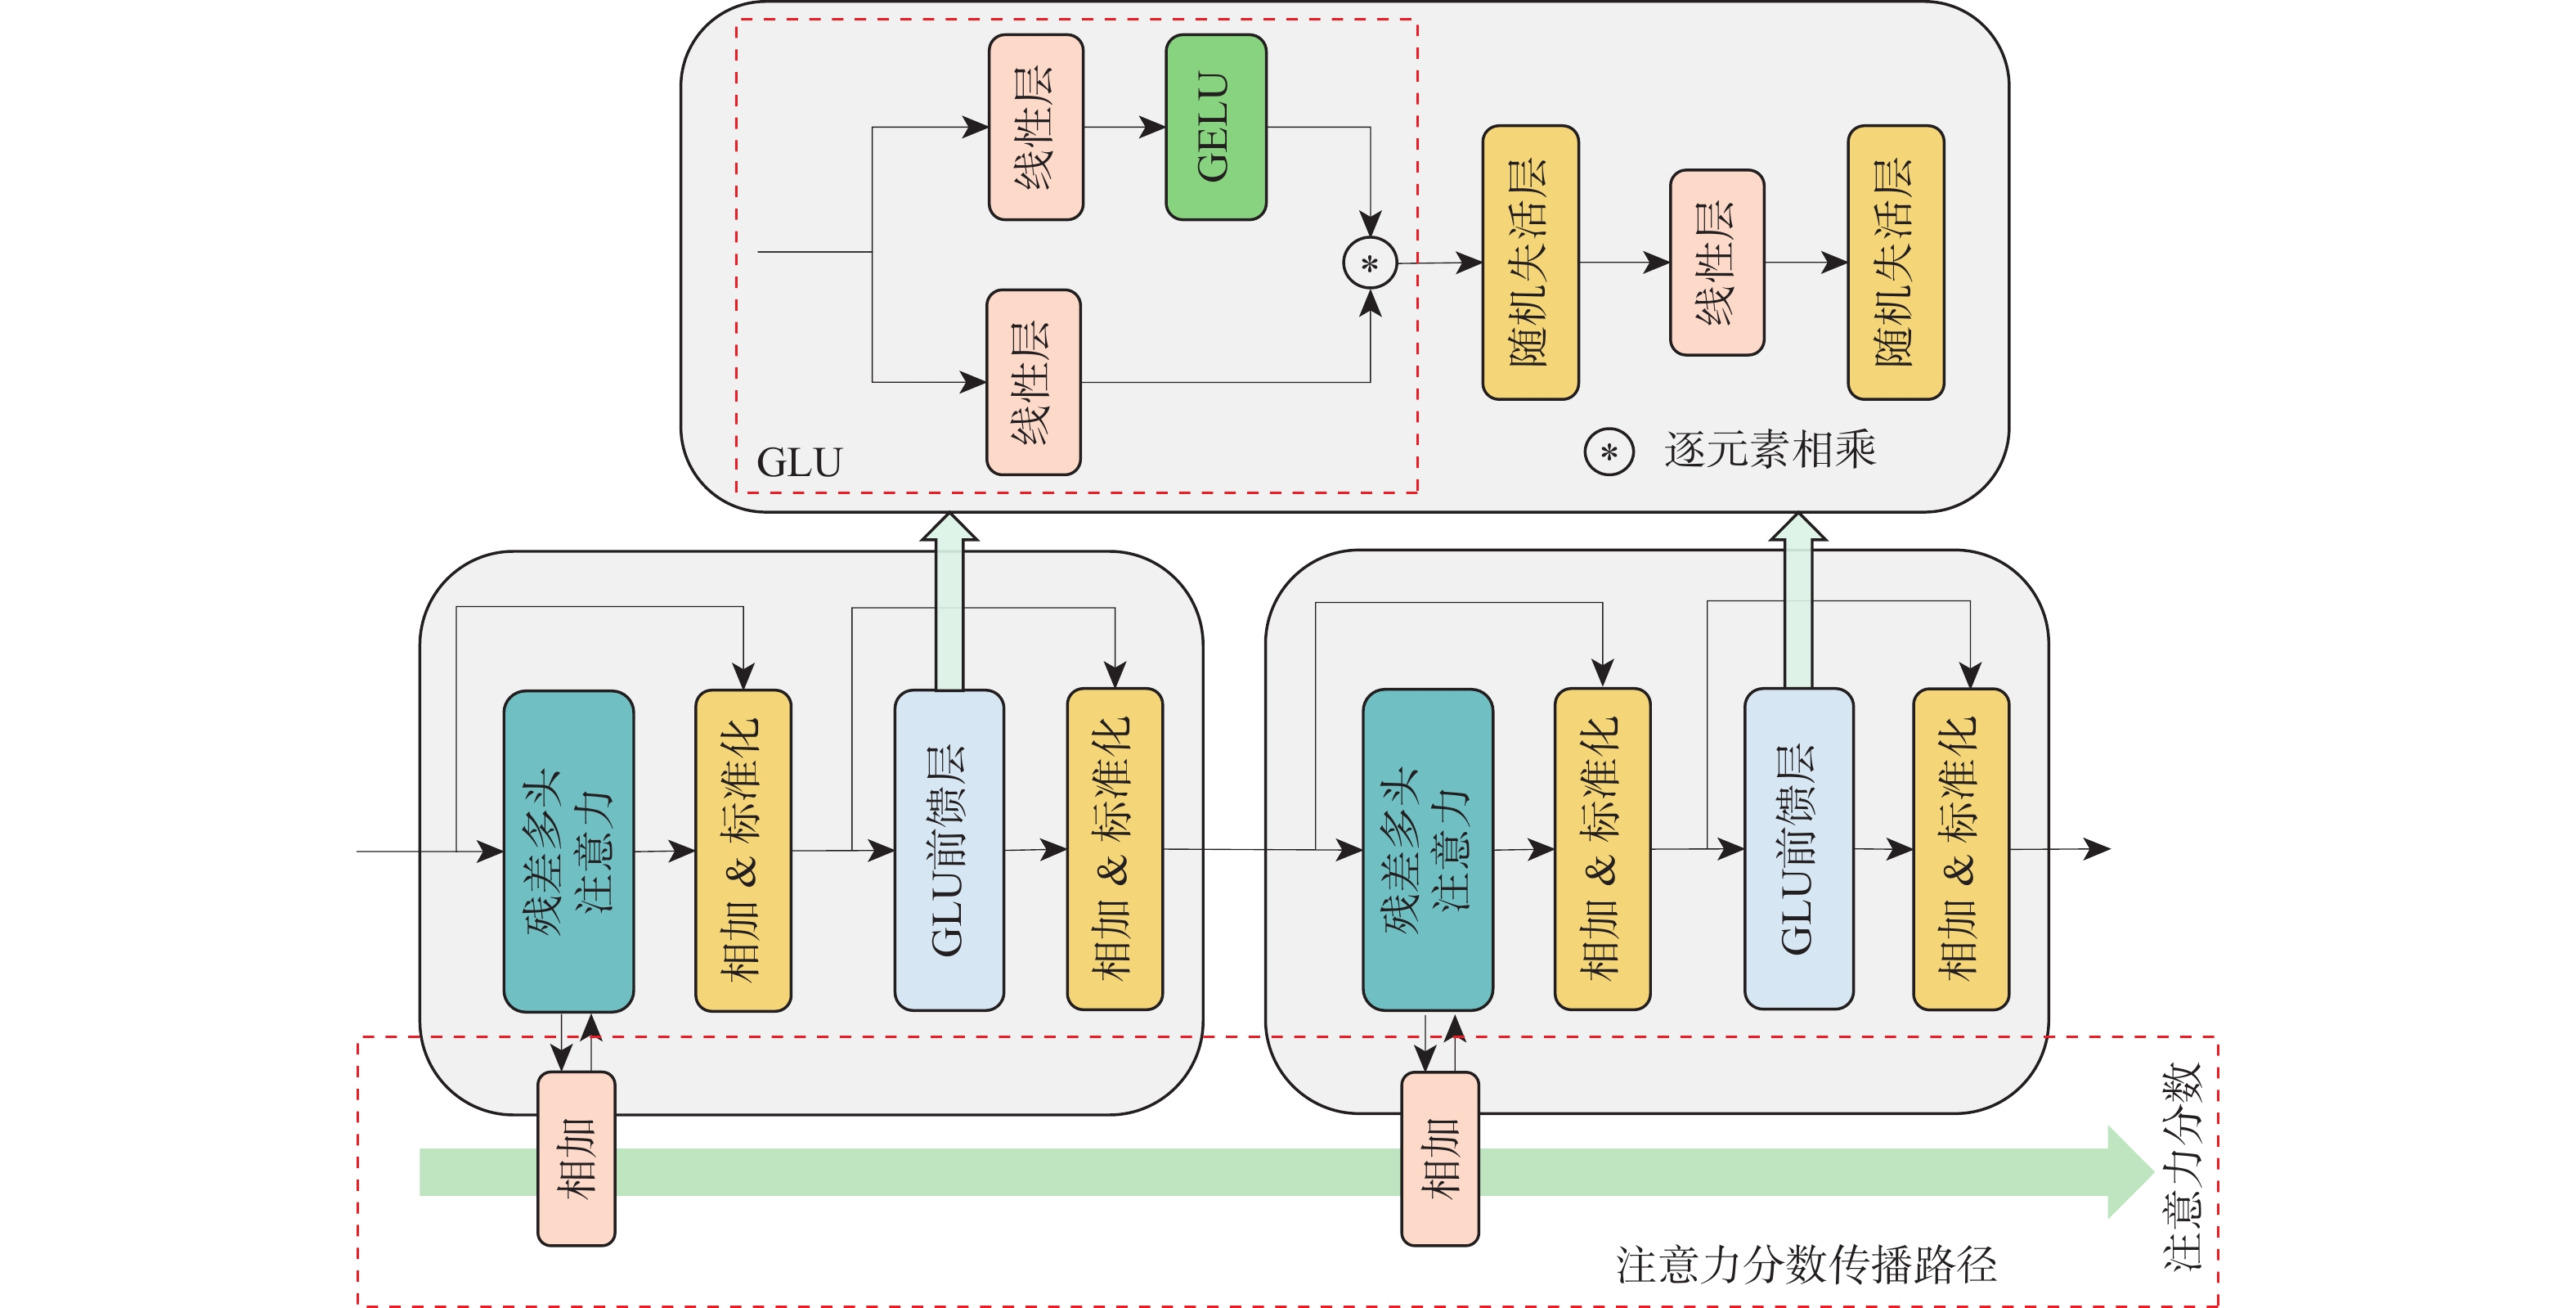
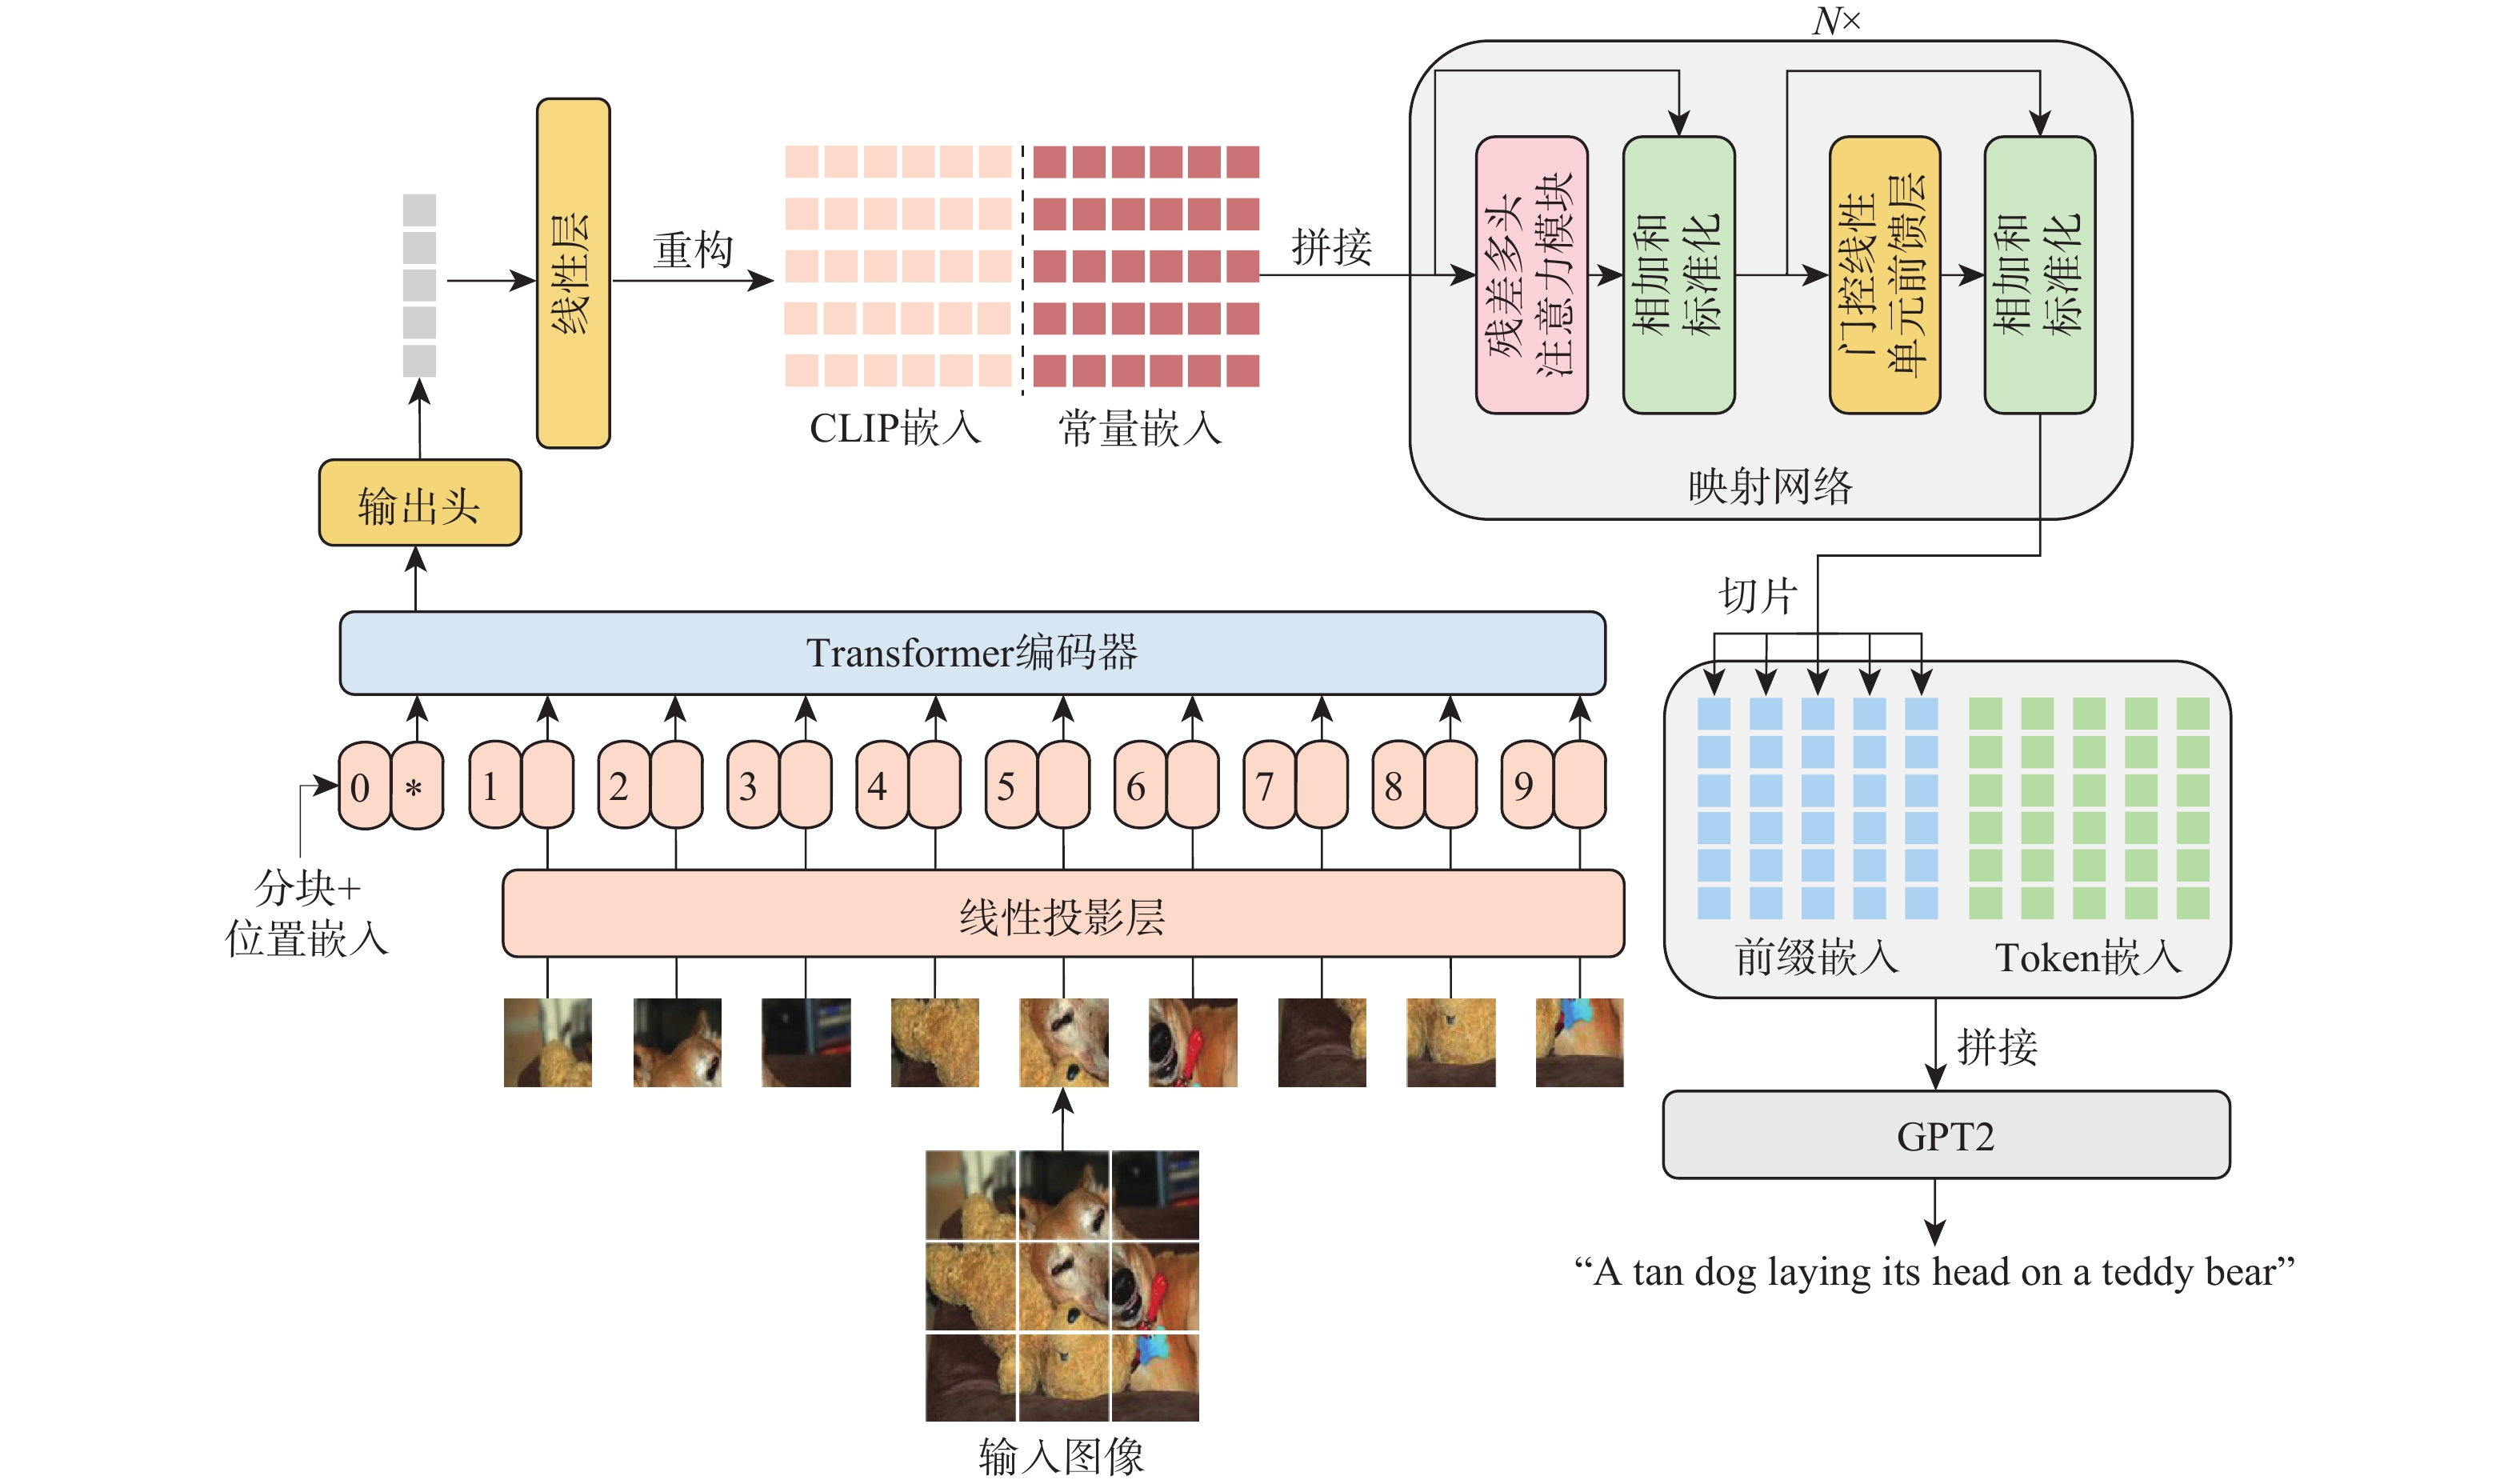
Natural language processing and computer vision are combined in the cross-modal job of image captioning. The model is required to generate an appropriate caption for the given image. To address this challenge, we proposed residual gated Transformer (RGFormer) as an enhancement of the Transformer architecture. The model, based on CLIP and RGFormer, CRM, is then proposed for image captioning. CRM utilizes the encoder of CLIP to extract image features as a prefix to the caption. RGFormer, a lightweight mapping network, projects the prefix into language space before feeding it into GPT-2 to produce captions. CLIP was trained on an extensive dataset comprising image-text pairs, which contains rich visual and semantic information and is exceptionally well-suited for vision-language tasks. The core idea of CRM is to reduce the disparity between visual and textual representations by using RGFormer to accomplish the cross-modal task. CRM could generate meaningful captions for large-scale datasets in a short training time without additional annotations or pre-training. Quantitative evaluation experiments show that CRM achieves results comparable to some advanced models on the COCO Caption dataset more efficiently.

| [1] |
Anderson P, He X D, Buehler C, et al. Bottom-up and top-down attention for image captioning and visual question answering[C]//Proceedings of the 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway Palo Alto: IEEE Press, 2018: 6077-6086.
|
| [2] |
Chen X L, Zitnick C L. Learning a recurrent visual representation for image caption generation[EB/OL]. (2014-11-20)[ 2024-12-18]. https://doi.org/10.48550/arXiv.1411.5654.
|
| [3] |
Li X J, Yin X, Li C Y, et al. Oscar: object-semantics aligned pre-training for vision-language tasks[C]//Computer Vision-ECCV 2020. Cham: Springer International Publishing, 2020: 121-137.
|
| [4] |
Stefanini M, Cornia M, Baraldi L, et al. From show to tell: a survey on deep learning-based image captioning[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023, 45(1): 539-559.
|
| [5] |
Tan H, Bansal M. LXMERT: learning cross-modality encoder representations from transformers[EB/OL]. (2019-12-03)[2024-12-20]. https://doi.org/10.48550/arXiv.1908.07490.
|
| [6] |
Xu K, Ba J L, Kiros R, et al. Show, attend and tell: neural image caption generation with visual attention[C]//International Conference on Machine Learning. New York: ACM, 2015: 2048-2057.
|
| [7] |
Yao T, Pan Y W, Li Y H, et al. Exploring visual relationship for image captioning[C]//Computer Vision-ECCV 2018. Cham: Springer International Publishing, 2018: 711-727.
|
| [8] |
Radford A, Kim J W, Hallacy C, et al. Learning transferable visual models from natural language supervision[C]//International Conference on Machine Learning. Virtual Event: PMLR, 2021: 8748-8763.
|
| [9] |
Chen X L, Fang H, Lin T Y, et al. Microsoft COCO captions: data collection and evaluation server[EB/OL]. (2015-04-03)[2024-12-20]. https://doi.org/10.48550/arXiv.1504.00325.
|
| [10] |
Lin T Y, Maire M, Belongie S, et al. Microsoft COCO: common objects in context[C]//Computer Vision-ECCV 2014. Cham: Springer International Publishing, 2014: 740-755.
|
| [11] |
Simonyan K, Zisserman A. Very deep convolutional networks for large-scale image recognition[EB/OL]. (2015-04-10)[2024-12-20]. https://arxiv.org/abs/1409.1556.
|
| [12] |
He K M, Zhang X Y, Ren S Q, et al. Deep residual learning for image recognition[C]//Proceedings of the 2016 IEEE Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2016: 770-778.
|
| [13] |
Ren S Q, He K M, Girshick R, et al. Faster R-CNN: towards real-time object detection with region proposal networks[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2017, 39(6): 1137-1149.
|
| [14] |
Zhou L, Palangi H, Zhang L, et al. Unified vision-language pre-training for image captioning and VQA[C]//Proceedings of the 34th AAAI Conference on Artificial Intelligence Palo Alto: AAAI Press, 2020: 13041-13049.
|
| [15] |
Conde M V, Turgutlu K. CLIP-art: contrastive pre-training for fine-grained art classification[C]//Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops. Piscataway: IEEE Press, 2021: 3951-3955.
|
| [16] |
Zhang R R, Zhang W, Fang R Y, et al. Tip-adapter: training-free adaption of CLIP for few-shot classification[C]//Computer Vision-ECCV 2022. Cham: Springer Nature Switzerland, 2022: 493-510.
|
| [17] |
Liu H D, Xu S Y, Fu J M, et al. CMA-CLIP: cross-modality attention CLIP for image-text classification[EB/OL]. (2021-12-09)[2024-12-21]. https://arxiv.org/abs/2112.03562.
|
| [18] |
Vidit V, Engilberge M, Salzmann M. CLIP the gap: a single domain generalization approach for object detection[C]//Proceedings of the 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2023: 3219-3229.
|
| [19] |
Teng Z, Duan Y N, Liu Y, et al. Global to local: clip-LSTM-based object detection from remote sensing images[J]. IEEE Transactions on Geoscience and Remote Sensing, 2022, 60: 5603113.
|
| [20] |
Gu X Y, Lin T Y, Kuo W C, et al. Open-vocabulary object detection via vision and language knowledge distillation[EB/OL]. (2022-05-12)[2024-12-21]. https://doi.org/10.48550/arXiv.2104.13921.
|
| [21] |
Anderson P, Fernando B, Johnson M, et al. SPICE: semantic propositional image caption evaluation[C]//Computer Vision-ECCV 2016. Cham: Springer International Publishing, 2016: 382-398.
|
| [22] |
Yong C, Fei H, Lian Z, et al. A hierarchical multimodal attention-based neural network for image captioning[J]. ACM SIGIR Forum, 2017, 51(CD): 889-892.
|
| [23] |
Ji J Y, Luo Y P, Sun X S, et al. Improving image captioning by leveraging intra-and inter-layer global representation in transformer network[C]//Proceedings of the AAAI Conference on Artificial Intelligence. Palo Alto: AAAI Press, 2021, 35(2): 1655-1663.
|
| [24] |
Luo Y P, Ji J Y, Sun X S, et al. Dual-level collaborative transformer for image captioning[C]//Proceedings of the AAAI Conference on Artificial Intelligence. Palo Alto: AAAI Press, 2021, 35(3): 2270-2277.
|
| [25] |
Hochreiter S, Schmidhuber J. Long short-term memory[J]. Neural Computation, 1997, 9(8): 1735-1780.
|
| [26] |
Vaswani A, Shazeer N, Parmar N, et al. Attention is all you need[C]//Advances in Neural Information Processing Systems. Long Beach: Curran Associates, Inc. , 2017, 30: 5998-6008.
|
| [27] |
Devlin J, Chang M W, Lee K, et al. BERT: pre-training of deep bidirectional transformers for language understanding[EB/OL]. (2019-05-24)[2024-12-24]. https://doi.org/10.48550/arXiv.1810.04805.
|
| [28] |
Lu J, Batra D, Parikh D, et al. Vilbert: pretraining task-agnostic visiolinguistic representations for vision-and-language tasks[J]. Advances in neural information processing systems, 2019, 32.
|
| [29] |
Radford A, Wu J, Child R, et al. Language models are unsupervised multitask learners[J]. OpenAI Blog, 2019, 1(8): 9.
|
| [30] |
Zhang P C, Li X J, Hu X W, et al. VinVL: revisiting visual representations in vision-language models[C]//Proceedings of the 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2021: 5575-5584.
|
| [31] |
Li X L, Liang P. Prefix-tuning: optimizing continuous prompts for generation[EB/OL]. (2021-01-01)[2024-12-25]. https://doi.org/10.48550/arXiv.2101.00190.
|
| [32] |
Dosovitskiy A, Beyer L, Kolesnikov A, et al. An image is worth 16x16 words: transformers for image recognition at scale[EB/OL]. V2. (2021-06-03)[2024-12-25]. https://doi.org/10.48550/arXiv.2010.11929.
|
| [33] |
Karpathy A, Li F F. Deep visual-semantic alignments for generating image descriptions[C]//Proceedings of the 2015 IEEE Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2015: 3128-3137.
|
| [34] |
Cho J, Lei J, Tan H, et al. Unifying vision-and-language tasks via text generation[C]//International Conference on Machine Learning. Virtual Event: PMLR, 2021: 1931-1942.
|
| [35] |
Sun L, Li Y W, Dong Y M. Learning from expert: vision-language knowledge distillation for unsupervised cross-modal hashing retrieval[C]//Proceedings of the 2023 ACM International Conference on Multimedia Retrieval. New York: ACM, 2023: 499-507.
|
| [36] |
Raffel C, Shazeer N, Roberts A, et al. Exploring the limits of transfer learning with a unified text-to-text transformer[J]. Journal of Machine Learning Research, 2020, 21(140): 1-67.
|
| [37] |
Lewis M, Liu Y H, Goyal N, et al. BART: denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension[EB/OL]. (2019-10-29)[2024-12-25]. https://doi.org/10.48550/arXiv.1910.13461.
|
| [38] |
Papineni K, Roukos S, Ward T, et al. Bleu: a method for automatic evaluation of machine translation[C]//Proceedings of the 40th Annual Meeting of the Association for Computational Linguistics. Philadelphia: Association for Computational Linguistics, 2002: 311-318.
|
| [39] |
Denkowski M, Lavie A. Meteor universal: language specific translation evaluation for any target language[C]//Proceedings of the Ninth Workshop on Statistical Machine Translation. Philadelphia: Association for Computational Linguistics, 2014: 376-380.
|
| [40] |
Vedantam R, Zitnick C L, Parikh D. CIDEr: consensus-based image description evaluation[C]//Proceedings of the 2015 IEEE Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2015: 4566-4575.
|
Figures(9) / Tables(2)
Copyright © Journal of Beijing University of Aeronautics and Astronautics
Address: Editorial Department of Journal of Beijing University of Aeronautics and Astronautics, 37 Xueyuan Road, Haidian District, Beijing Post Code: 100191 Email: jbuaa@buaa.edu.cn
Supported by:
Beijing Renhe Information Technology Co., Ltd.



 DownLoad: