


-
摘要:
可在监控探头分布稀疏区域协同分析无人机拍摄图像与固定监控视频图像,基于行人图像的跨视角身份认定实现对目标持续追踪的巡检任务。无人机俯视视角与地面监控的平视视角存在显著差异,导致基于传统监控场景设计的图像检索算法在地空跨视角场景中迁移性能受限。现有空地行人检索方法主要聚焦于缓解跨视角引起的表观差异,而对行人属性特征的挖掘与分析尚未充分深入。为解决上述问题,提出基于大模型属性解析的空地行人检索方法。基于多模态大模型构建行人解析模块,生成细粒度语义属性并设计属性三元组损失实现跨视角语义对齐;引入视角解耦架构,通过分层减法分离剥离视角相关特征,并施加正交损失约束特征独立性;引入多尺度扩增Transformer,结合多尺度扩张注意力与全局自注意力优化计算复杂度与感受野平衡,降低模型参数量。在AG-ReID.v1、AG-ReID.v2、CARGO数据集上的实验表明:所提方法能够有效提升空地行人检索任务在Rank-1、mAP与mINP指标上的性能,证明了该方法的有效性。
Abstract:Synergistic analysis of drone-captured imagery and fixed surveillance video enables continuous tracking of targets in inspection tasks, achieving cross-view person re-identification in areas where surveillance probes are sparsely distributed. The transferability of image retrieval algorithms created for conventional surveillance situations to aerial-ground cross-view environments is limited by the notable discrepancy between the horizontal view of ground surveillance and the bird’s-eye view of drones. Existing aerial-ground pedestrian retrieval methods primarily focus on mitigating the appearance discrepancies caused by cross-view variations, while the mining and analysis of person attribute characteristics remain insufficiently explored. To address these issues, this paper proposes a aerial-ground pedestrian retrieval method based on large model attribute parsing. A person parsing module is constructed based on a multi-modal large model to generate fine-grained semantic attributes, and an attribute triplet loss is designed to achieve cross-view semantic alignment. A view decoupling architecture is introduced to separate view-specific features through hierarchical subtraction, with an orthogonal loss applied to constrain feature independence. A multi-scale dilated Transformer is incorporated, combining multi-scale dilated attention with global self-attention to optimize the balance between computational complexity and receptive field, thereby reducing model parameters. The effectiveness of the methodology is confirmed by experiments on the AG-ReID.v1, AG-ReID.v2, and CARGO datasets, which show that the suggested strategy successfully increases performance on Rank-1, mAP, and mINP metrics in aerial-ground pedestrian retrieval tasks.
-
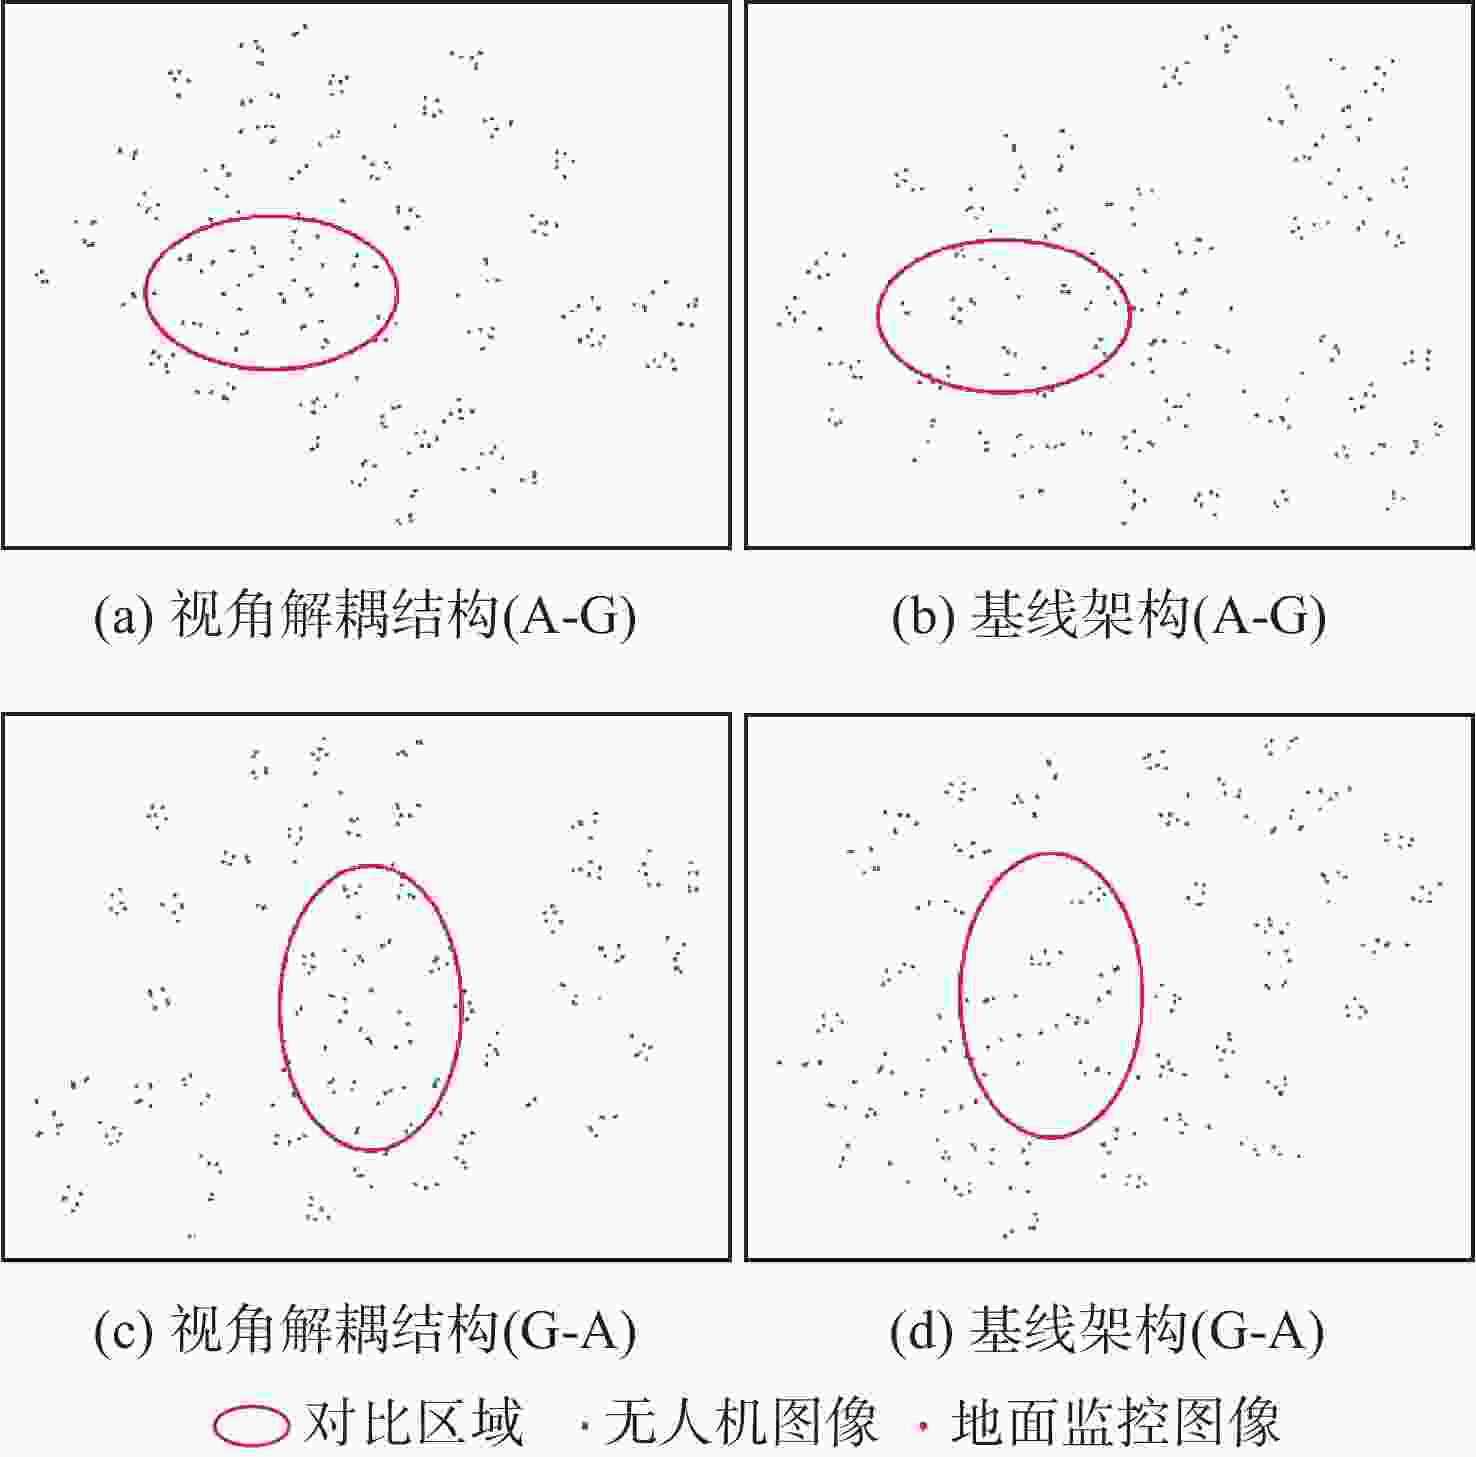
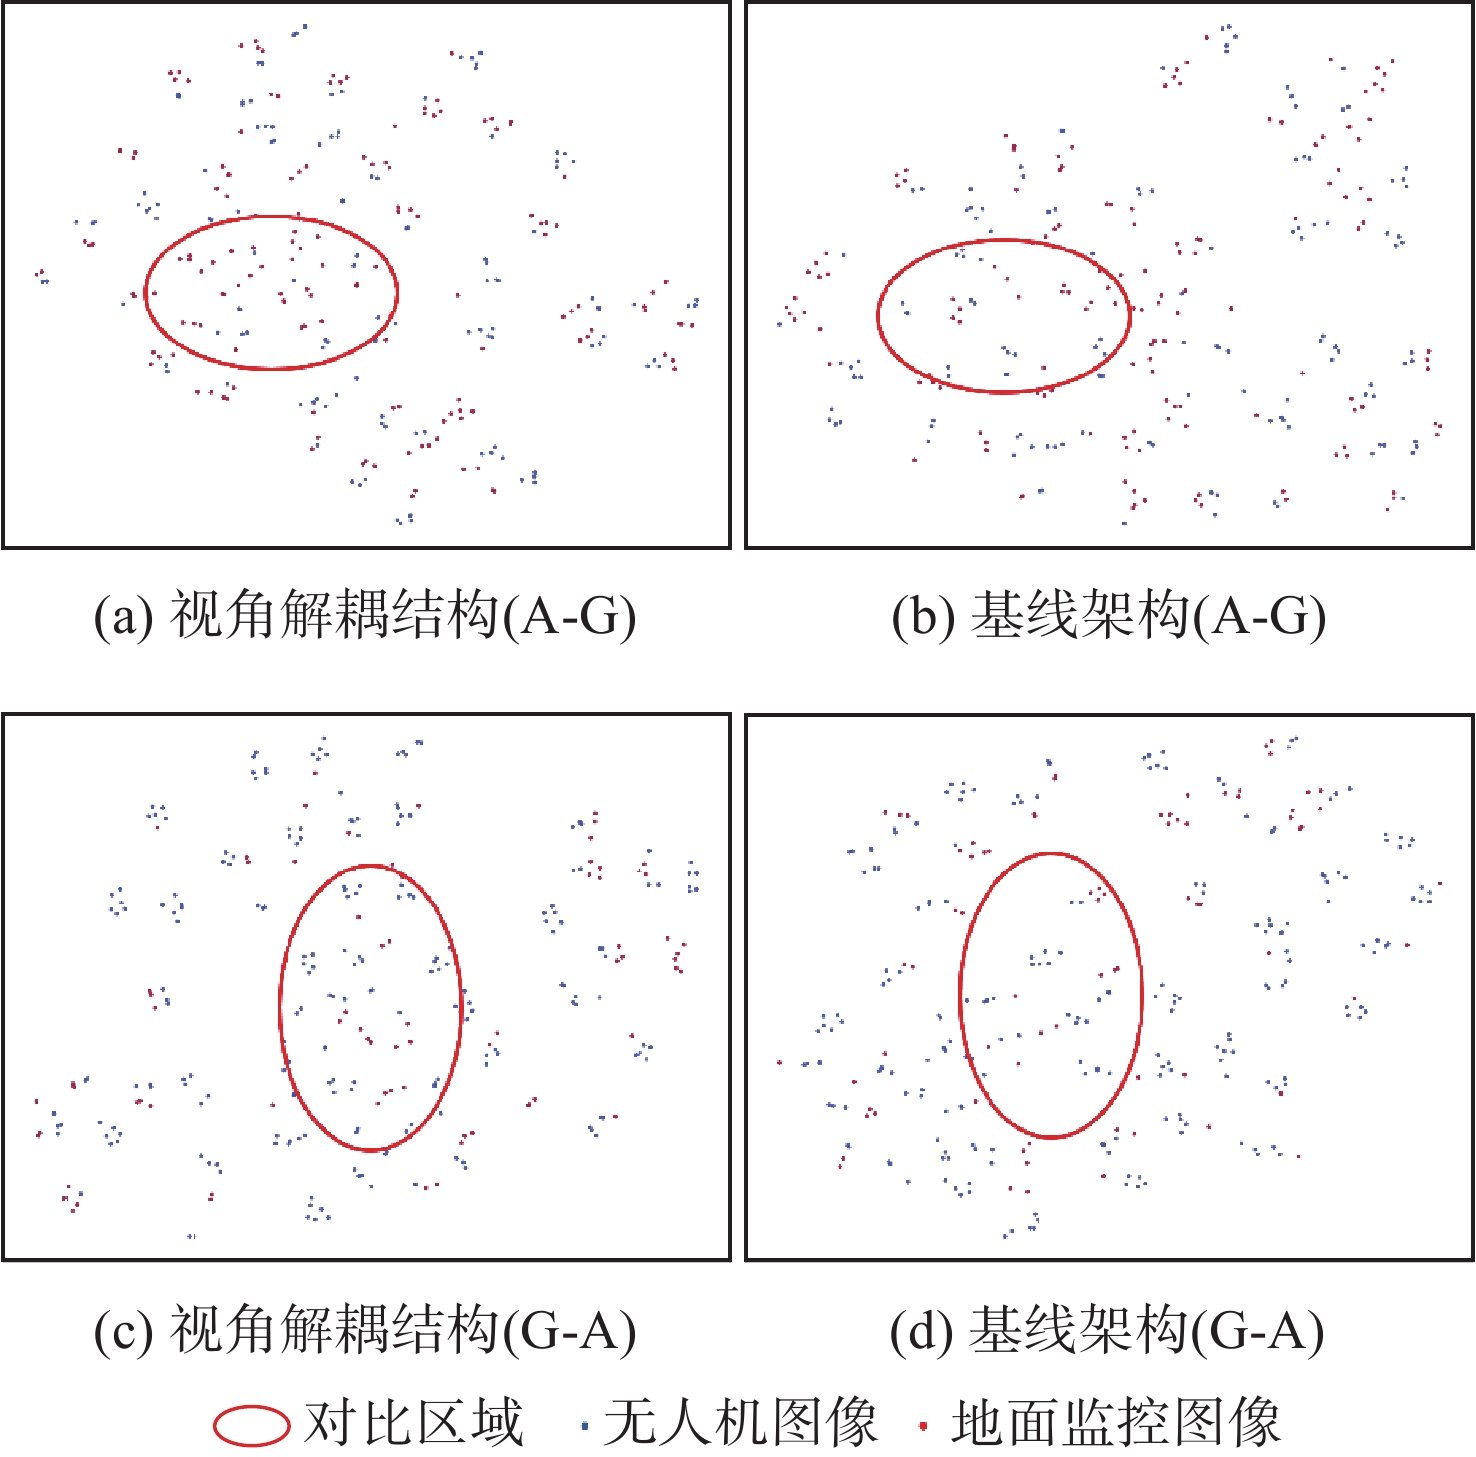
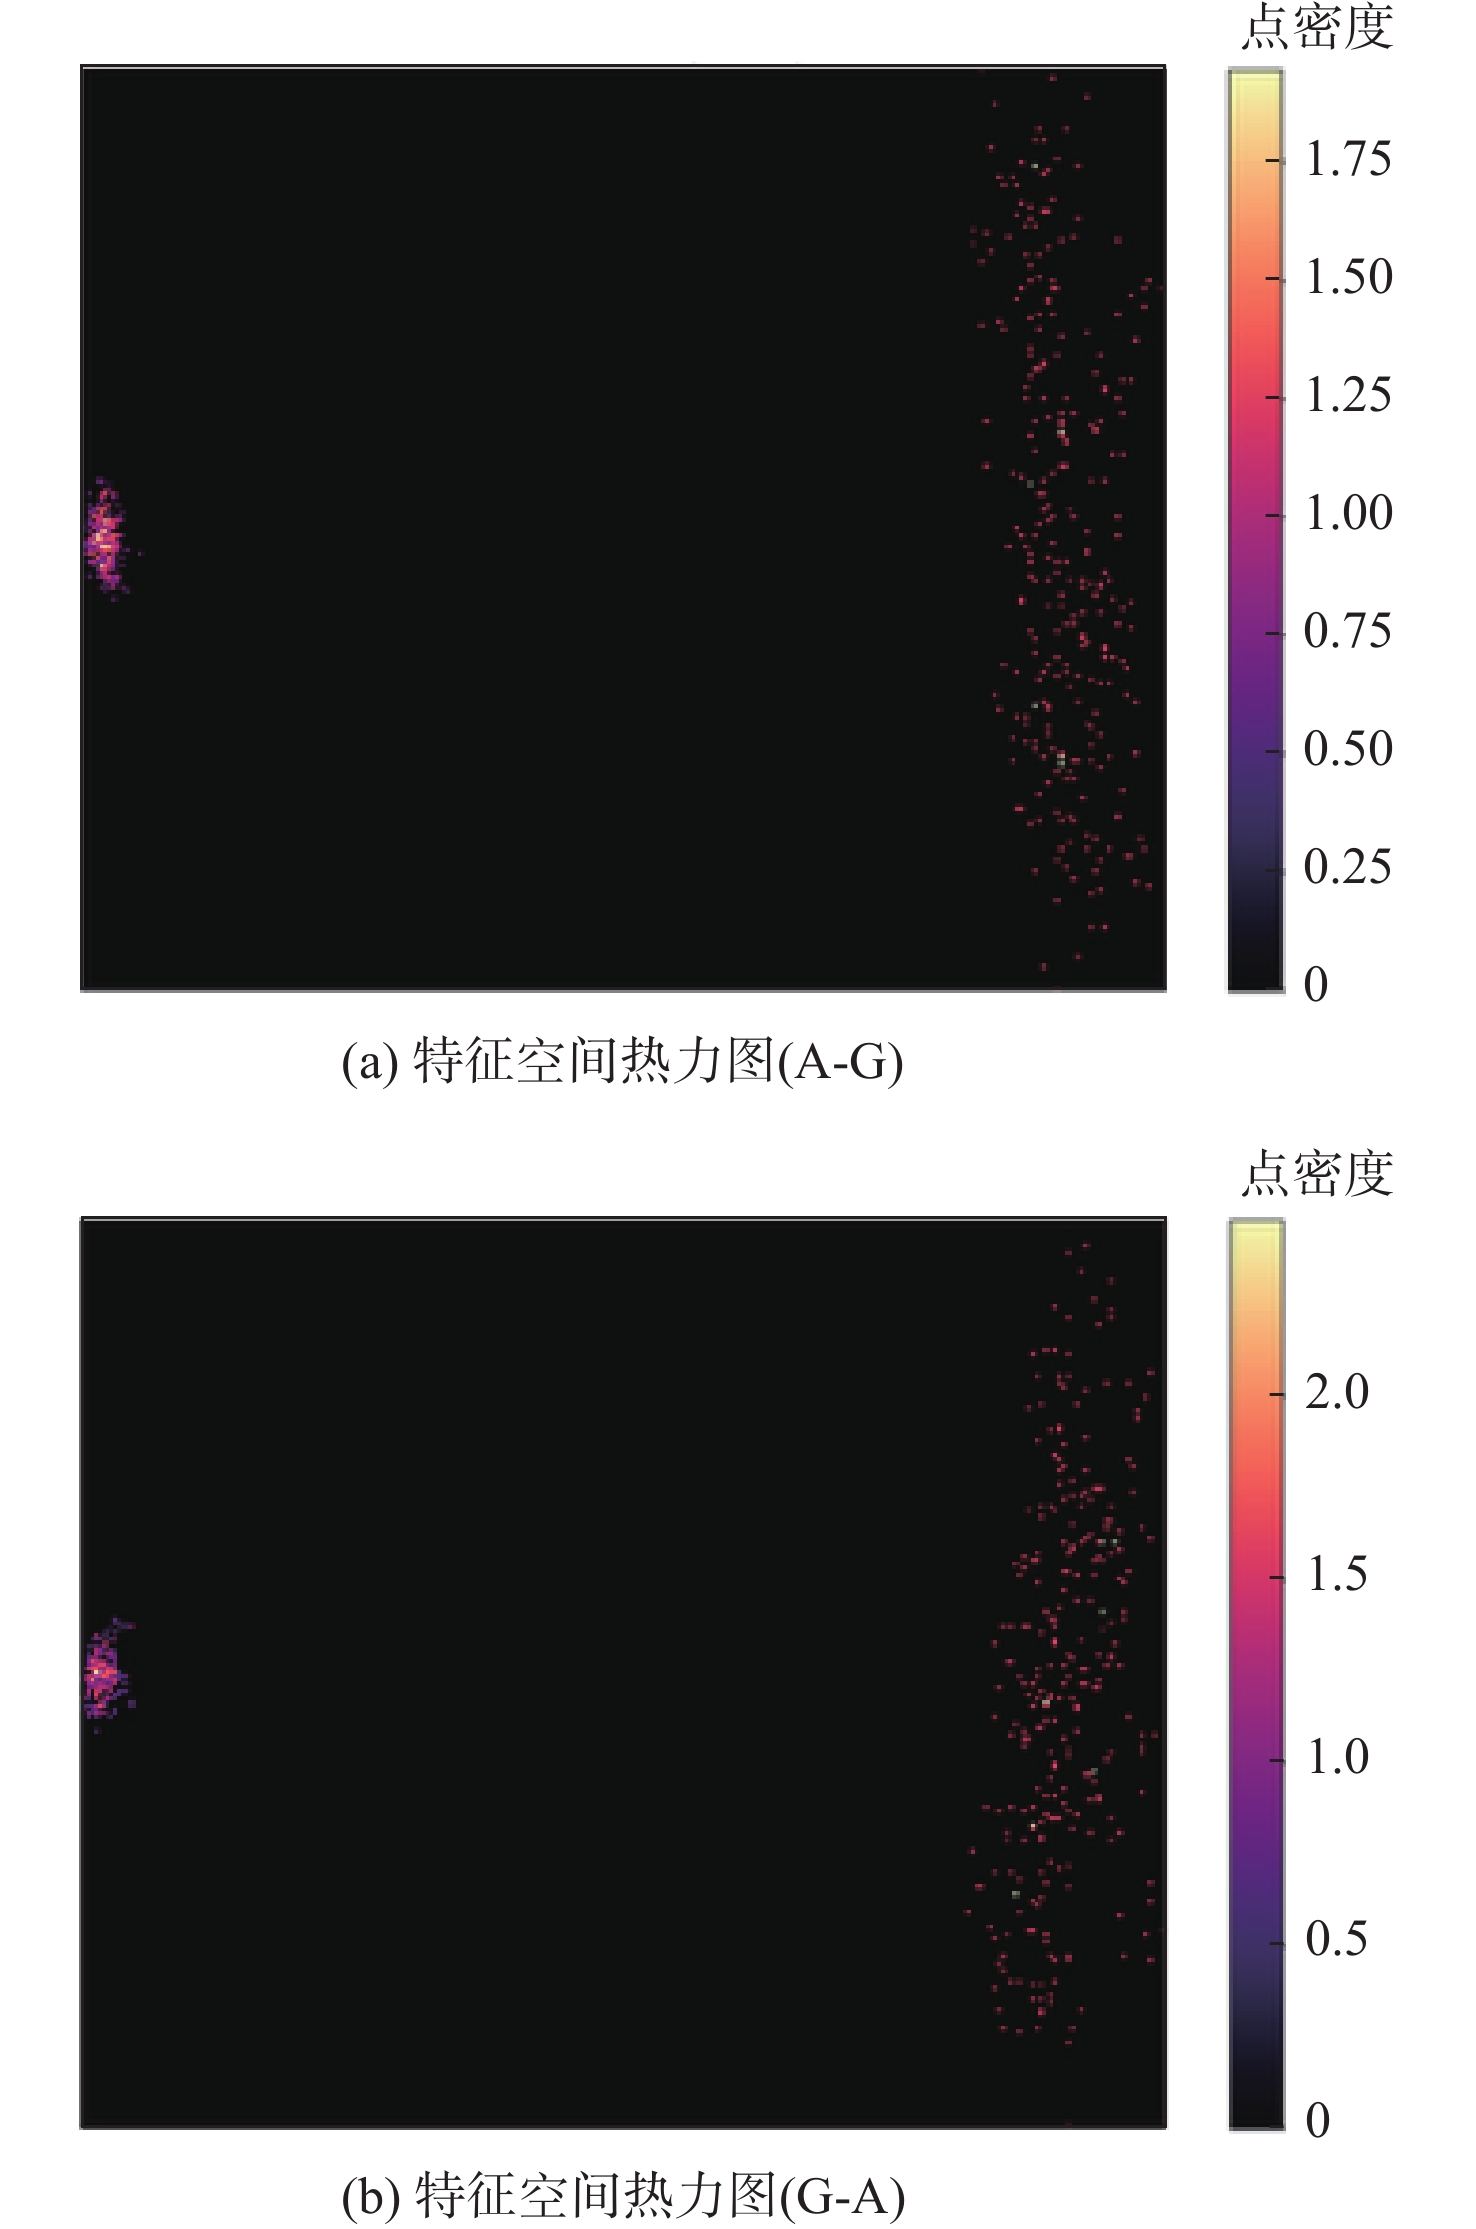
图 4 AG-ReID.v1测试t-SNE可视化结果
Figure 4. t-SNE visualization results of AG-ReID.v1 testing
表 1 AG-ReID.v1数据集实验结果
Table 1. Experimental results on AG-ReID.v1 dataset
方法 Rank-1/% mAP/% mINP/% A-G G-A A-G G-A A-G G-A OSNet[23] 72.59 74.22 58.32 60.99 Bo[24] 70.01 71.20 55.47 58.83 SBS[25] 73.54 73.70 59.77 62.27 VV[26-27] 77.22 79.73 67.23 69.83 41.43 42.37 ViT[28] 81.28 82.64 72.38 73.35 TransReID[7] 81.80 83.40 73.10 74.60 FusionReID[29] 80.40 82.40 71.40 74.20 CLIP-ReID[30] 79.44 84.20 70.55 73.05 PCL-CLIP[31] 82.16 86.90 73.11 76.28 Explain[13] 81.47 82.85 72.61 73.39 VDT[15] 83.00 84.62 74.06 76.28 50.31 49.51 DTST[32] 83.48 84.72 74.51 76.05 49.86 50.04 SD-ReID[16] 85.16 85.97 75.40 77.02 51.35 50.42 本文方法 86.35 86.32 75.82 77.11 51.44 50.73  下载: 导出CSV
表 3 CARGO数据集实验结果
Table 3. Experimental results on CARGO dataset
方法 Rank-1/% mAP/% mINP/% A-G ALL G-G A-A A-G ALL G-G A-A A-G ALL G-G A-A SBS[25] 31.25 50.32 72.31 67.50 29.00 43.09 62.99 49.73 18.71 29.76 48.24 29.32 PCB[33] 34.40 51.00 74.10 55.00 30.40 44.50 67.60 44.60 20.10 32.20 55.10 27.00 BoT[24] 36.25 54.81 77.68 65.00 32.56 46.49 66.47 49.79 21.46 32.40 51.34 29.82 MGN[2] 31.87 54.81 83.93 65.00 33.47 49.08 71.05 52.96 24.64 36.52 55.20 36.78 VV[26-27] 31.25 45.83 72.31 67.50 29.00 38.84 62.99 49.73 18.71 39.57 48.24 29.32 AGW[22] 43.57 60.26 81.25 67.50 40.90 53.44 71.66 56.48 29.39 40.22 58.09 40.40 ViT[28] 43.13 61.54 82.14 80.00 40.11 53.54 71.34 64.47 28.20 39.62 57.55 47.07 VDT[15] 45.00 60.58 76.79 82.50 42.08 54.61 71.97 64.67 29.66 41.37 61.42 45.09 DTST[32] 50.63 64.42 78.57 80.00 43.39 55.73 72.40 63.31 29.46 41.92 62.10 44.67 SD-ReID[16] 53.12 65.06 81.25 82.50 46.44 57.47 74.08 67.70 33.03 44.21 63.10 51.90 本文方法 54.57 66.25 83.46 82.73 47.01 58.83 75.04 68.21 33.52 45.51 63.60 52.24
下载: 导出CSV
表 4 消融实验
Table 4. Ablation experiment
方法 Rank-1/% mAP/% mINP/% 参数量 A-G G-A A-G G-A A-G G-A TransReID 72.63 78.36 62.61 65.37 41.59 42.30 8.050×10⁻⁷ +属性 80.11 82.64 70.98 72.22 46.78 47.59 1.904×10⁻⁸ +视角解耦 86.20 86.83 76.21 77.38 51.12 50.10 1.957×10⁻⁸ +扩增Transformer 86.35 86.32 75.82 77.11 51.44 50.73 1.972×10⁻⁸
下载: 导出CSV
表 5 模型推理效率参数
Table 5. Model inference efficiency parameters
方法 帧率/(帧·s−1) 推理时间/s 参数量 浮点运算速度/
109 s−1TransReID 1363 7.33×10⁻⁴ 8.050×10⁷ 11.13 +属性 758 1.32×10⁻³ 1.904×10⁸ 14.44 +视角解耦 749 1.33×10⁻³ 1.957×10⁸ 14.71 +扩增Transformer 916 1.09×10⁻³ 1.729×10⁸ 12.04
下载: 导出CSV
-
[1] Sun Y F, Zheng L, Yang Y, et al. Beyond part models: person retrieval with refined part pooling (and a strong convolutional baseline)[C]//Proceedings of the Computer Vision-ECCV 2018. Berlin: Springer, 2018: 501-518. [2] Wang G S, Yuan Y F, Chen X, et al. Learning discriminative features with multiple granularities for person re-identification[C]// Proceedings of the 26th ACM International Conference on Multimedia. New York: ACM, 2018: 274-282. [3] Rao Y M, Chen G Y, Lu J W, et al. Counterfactual attention learning for fine-grained visual categorization and re-identification[C]//Proceedings of the IEEE/CVF International Conference on Computer Vision. Piscataway: IEEE Press, 2022: 1005-1014. [4] Zheng L, Shen L Y, Tian L, et al. Scalable person re-identification: a benchmark[C]//Proceedings of the IEEE International Conference on Computer Vision. Piscataway: IEEE Press, 2016: 1116-1124. [5] Wei L H, Zhang S L, Gao W, et al. Person transfer GAN to bridge domain gap for person re-identification[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2018: 79-88. [6] Vaswani A, Shazeer N, Parmar N, et al. Attention is all you need[C]//Proceedings of the 31st International Conference on Neural Information Processing Systems. Berlin: Springer, 2017: 6000-6010. [7] He S T, Luo H, Wang P C, et al. TransReID: Transformer-based object re-identification[C]//Proceedings of the IEEE/CVF International Conference on Computer Vision. Piscataway: IEEE Press, 2022: 14993-15002. [8] Zhang G W, Zhang P P, Qi J Q, et al. HAT: hierarchical aggregation Transformers for person re-identification[C]//Proceedings of the 29th ACM International Conference on Multimedia. New York: ACM, 2021: 516-525. [9] Chen Y, Xia S X, Zhao J Q, et al. ResT-ReID: Transformer block-based residual learning for person re-identification[J]. Pattern Recognition Letters, 2022, 157: 90-96. [10] Zhu H W, Ke W J, Li D, et al. Dual cross-attention learning for fine-grained visual categorization and object re-identification[C]// Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2022: 4682-4692. [11] Zhu K, Guo H Y, Zhang S L, et al. AAformer: auto-aligned transformer for person re-identification[J].IEEE Transactions on Neural Networks and Learning Systems, 2024, 35(12): 17307-17317. [12] Schumann A, Metzler J. Person re-identification across aerial and ground-based cameras by deep feature fusion[J]. Automatic Target Recognition XXVII, 2017, 10202: 102020A. [13] Nguyen H, Nguyen K, Sridharan S, et al. Aerial-ground person re-ID[C]//Proceedings of the IEEE International Conference on Multimedia and Expo. Piscataway: IEEE Press, 2023: 2585-2590. [14] Nguyen H, Nguyen K, Sridharan S, et al. AG-ReID. v2: bridging aerial and ground views for person re-identification[J]. IEEE Transactions on Information Forensics and Security, 2024, 19: 2896-2908. [15] Zhang Q, Wang L, Patel V M, et al. View-decoupled transformer for person re-identification under aerial-ground camera network[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2024: 22000-22009. [16] Wang Y H, Hu X, Wang L X, et al. SD-ReID: view-aware stable diffusion for aerial-ground person re-identification[EB/OL]. (2025-05-14)[2025-10-10]. https://arxiv.org/abs/2504.09549. [17] Zheng A H, Pan P, Li H C, et al. Progressive attribute embedding for accurate cross-modality person re-ID[C]//Proceedings of the 30th ACM International Conference on Multimedia. New York: ACM, 2022: 4309-4317. [18] Tan W T, Ding C X, Jiang J Y, et al. Harnessing the power of MLLMs for transferable text-to-image person ReID[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2024: 17127-17137. [19] Yang S Y, Zhou Y N, Zheng Z D, et al. Towards unified text-based person retrieval: a large-scale multi-attribute and language search benchmark[C]//Proceedings of the 31st ACM International Conference on Multimedia. New York: ACM, 2023: 4492-4501. [20] Jiao J Y, Tang Y M, Lin K Y, et al. DilateFormer: multi-scale dilated Transformer for visual recognition[J]. IEEE Transactions on Multimedia, 2023, 25: 8906-8919. [21] Zeng A H, Xu B, Wang B W, et al. ChatGLM: a family of large language models from GLM-130B to GLM-4 all tools[EB/OL]. (2024-07-30)[2025-10-10]. https://arxiv.org/abs/2406.12793. [22] Ye M, Shen J B, Lin G J, et al. Deep learning for person re-identification: a survey and outlook[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022, 44(6): 2872-2893. [23] Zhou K Y, Yang Y X, Cavallaro A, et al. Learning generalisable omni-scale representations for person re-identification[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2021, 2021: 3069237. [24] Luo H, Gu Y Z, Liao X Y, et al. Bag of tricks and a strong baseline for deep person re-identification[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops. Piscataway: IEEE Press, 2019: 1487-1495. [25] He L X, Liao X Y, Liu W, et al. FastReID: a pytorch toolbox for general instance re-identification[C]// Proceedings of the 31st ACM International Conference on Multimedia. New York: ACM, 2023: 9664-9667. [26] Kuma R, Weill E, Aghdasi F, et al. Vehicle re-identification: an efficient baseline using triplet embedding[C]// Proceedings of the International Joint Conference on Neural Networks. Piscataway: IEEE Press, 2019: 1-9. [27] Kumar R, Weill E, Aghdasi F, et al. A strong and efficient baseline for vehicle re-identification using deep triplet embedding[J]. Journal of Artificial Intelligence and Soft Computing Research, 2020, 10(1): 27-45. [28] Dosovitskiy A. An image is worth 16x16 words: Transformers for image recognition at scale[EB/OL]. (2021-06-03)[2025-10-10]. https://arxiv.org/abs/2010.11929. [29] Wang Y H, Zhang P P, Liu X H, et al. Unity is strength: unifying convolutional and transformeral features for better person re-identification[J]. IEEE Transactions on Intelligent Transportation Systems, 2025, 26(3): 3713-3723. [30] Li S Y, Sun L, Li Q L. CLIP-ReID: exploiting vision-language model for image re-identification without concrete text labels[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2023, 37(1): 1405-1413. [31] Li J C, Gong X J. Prototypical contrastive learning-based CLIP fine-tuning for object re-identification[EB/OL]. (2025-01-14)[2025-10-10]. https://arxiv.org/abs/2310.17218. [32] Wang Y H, Pishgar M. Dynamic token selection for aerial-ground person re-identification[EB/OL]. (2024-12-25)[2025-10-10]. https://arxiv.org/abs/2412.00433. [33] Sun Y F, Zheng L, Li Y L, et al. Learning part-based convolutional features for person re-identification[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2021, 43(3): 902-917. -

 下载:

 点击查看大图
计量
- 文章访问数: 239
- HTML全文浏览量: 125
- PDF下载量: 4
- 被引次数: 0
