


Fine-grained semantic-enhanced cross-modal image-text retrieval method for civil aviation
-
摘要:
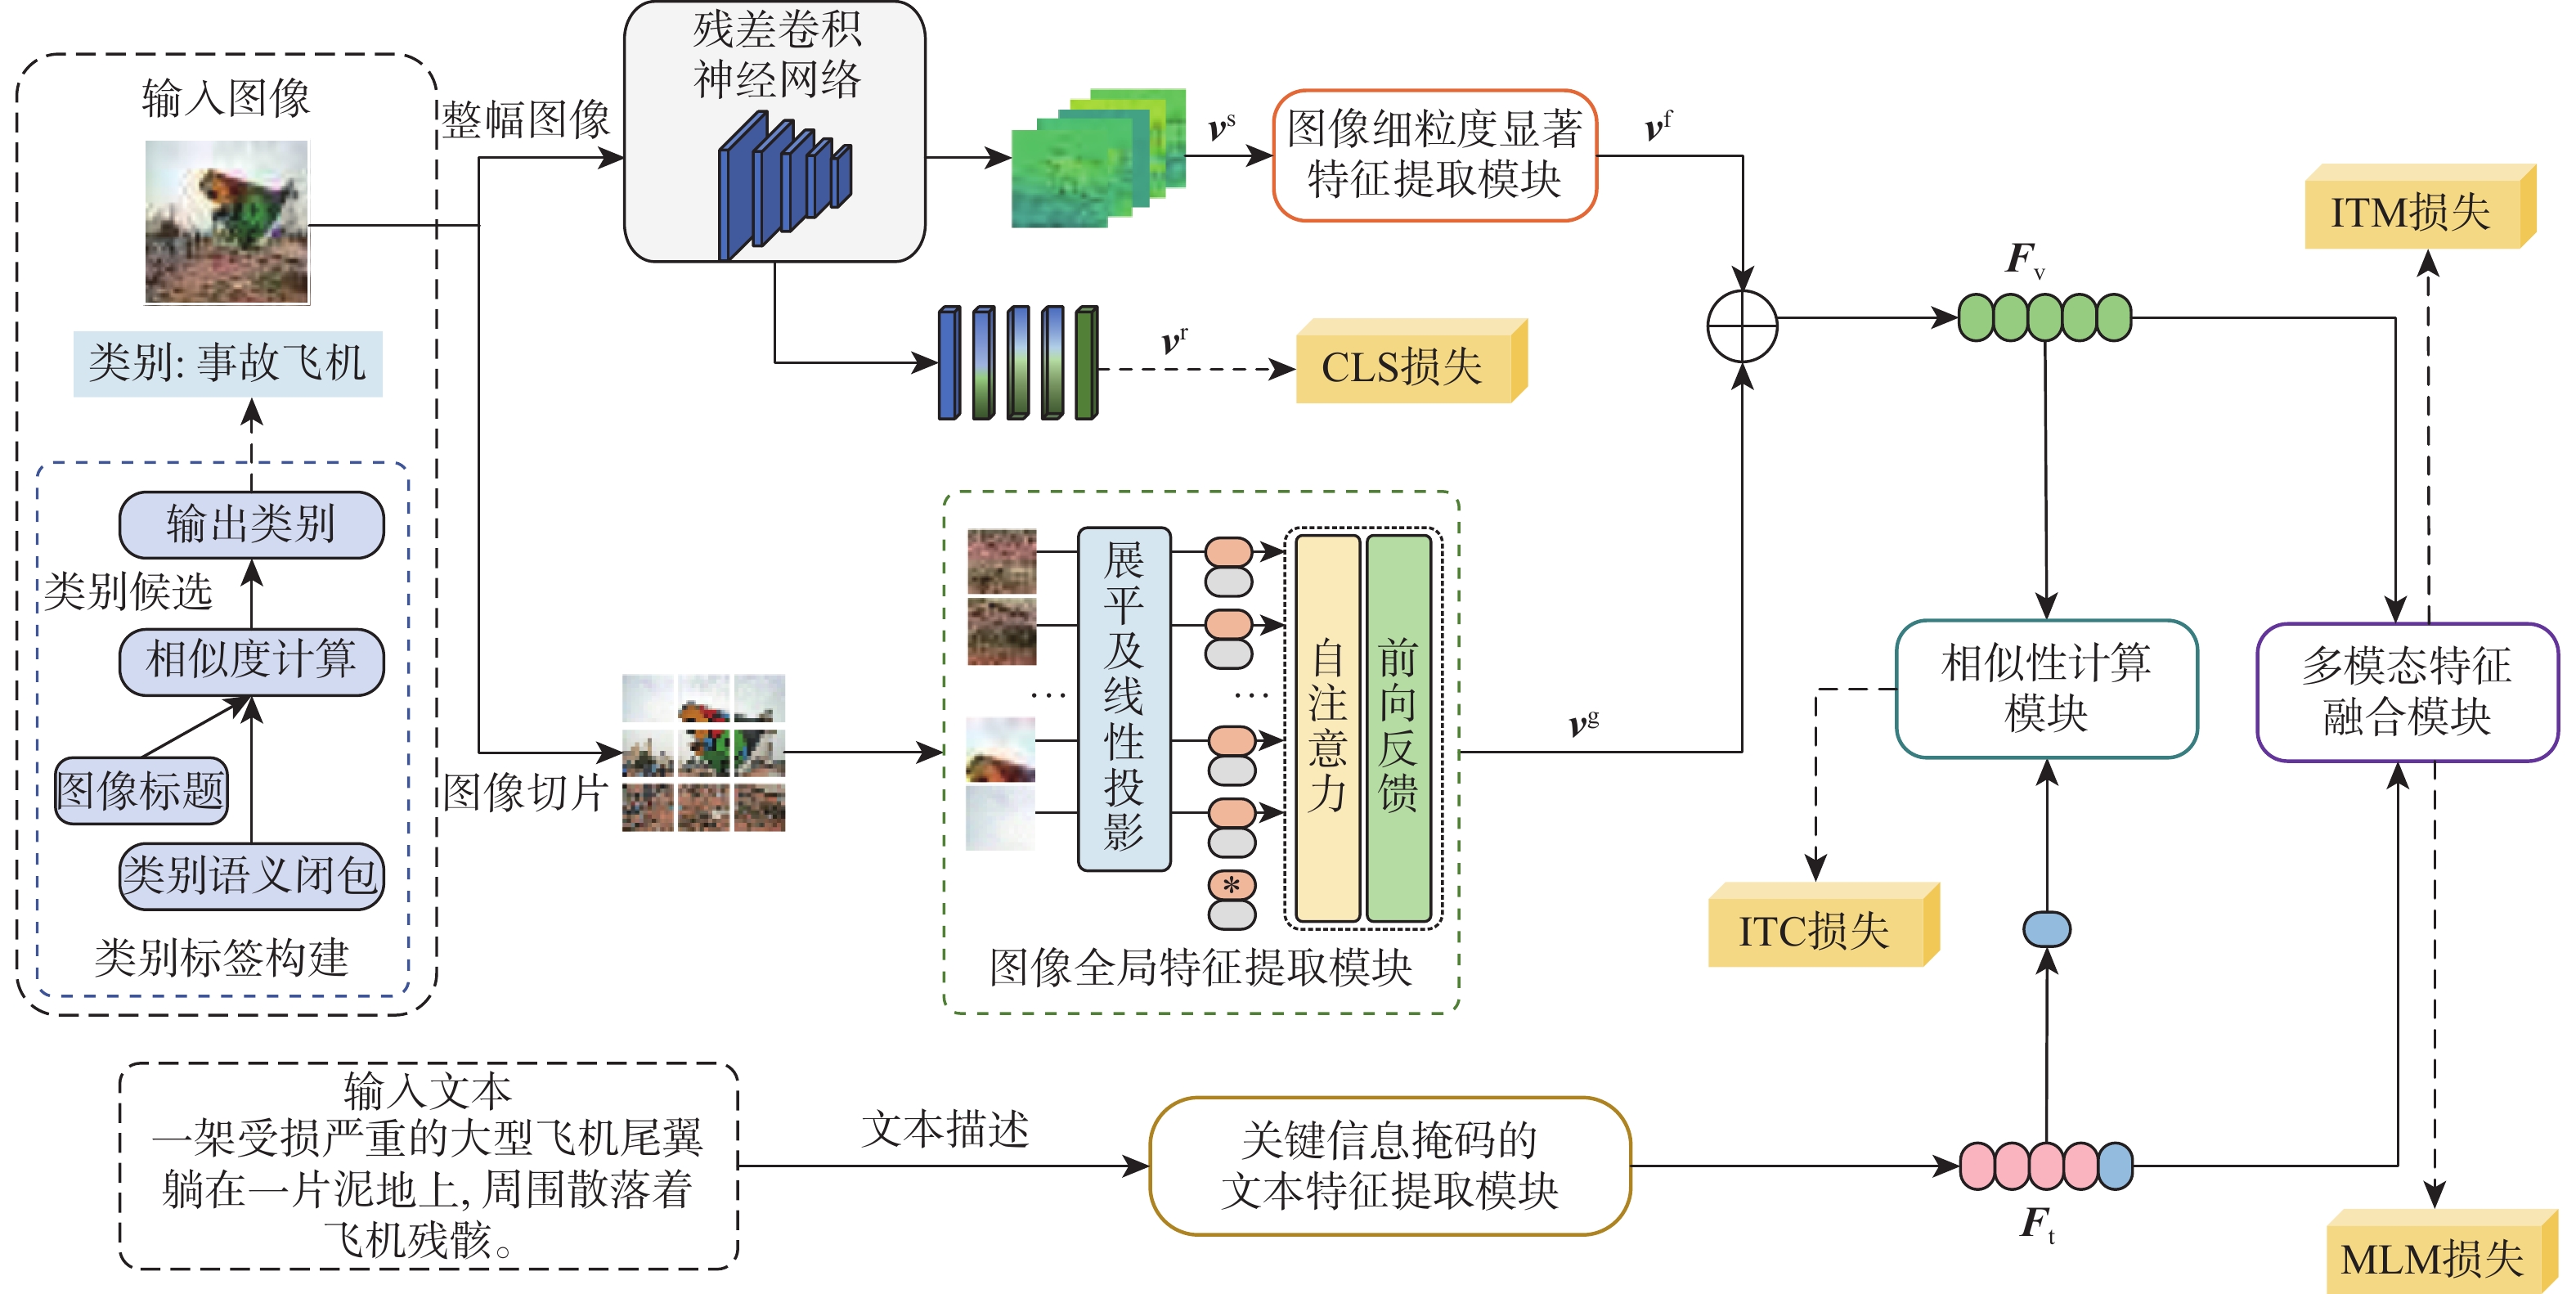
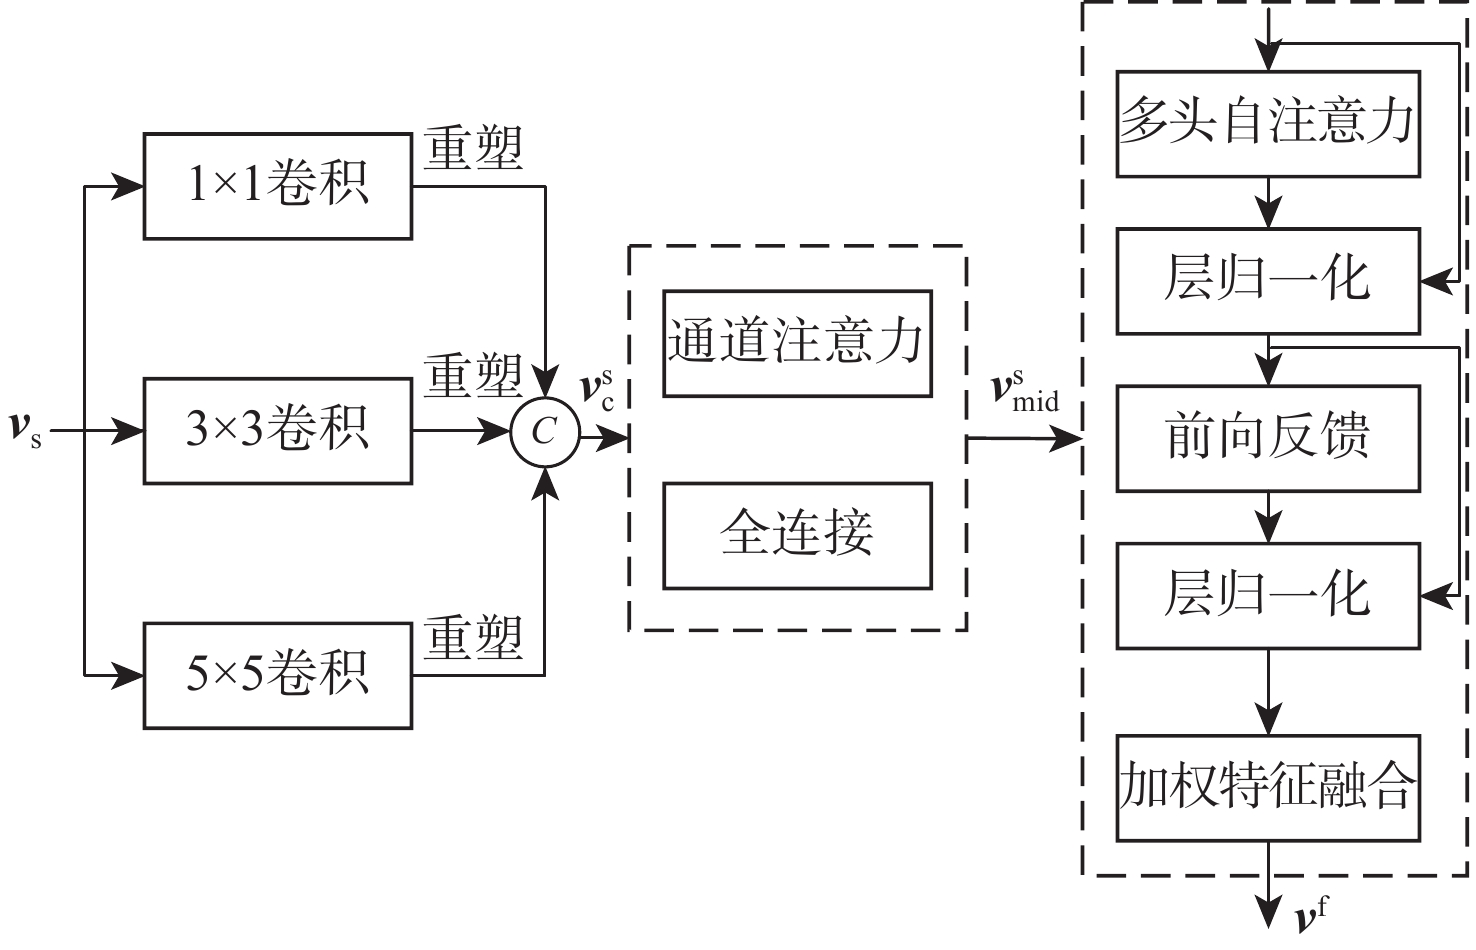
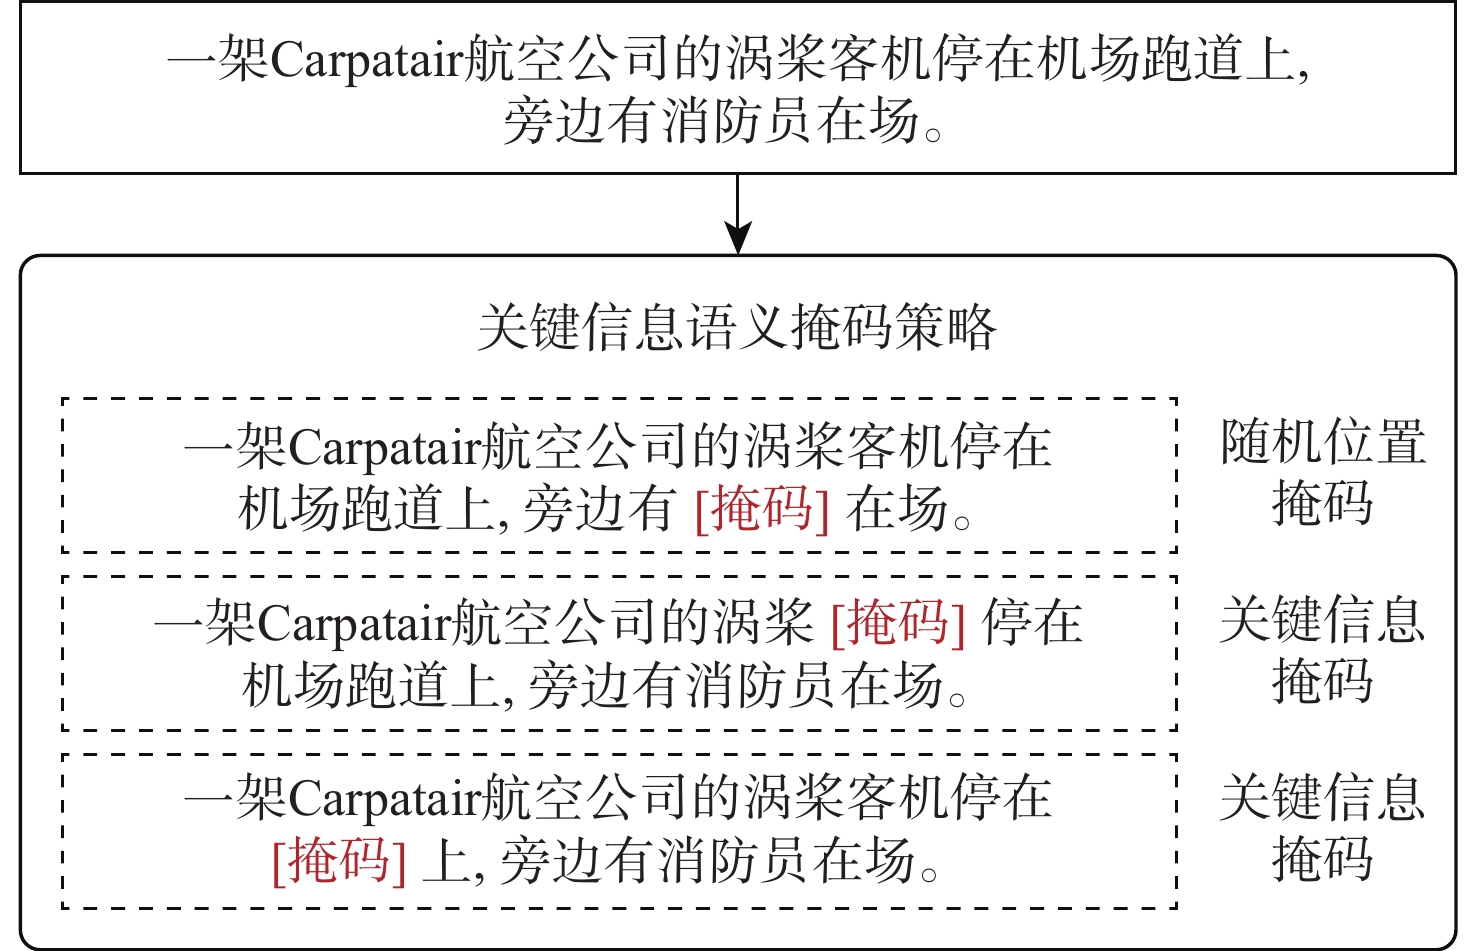
低空经济和民用航空领域在安全保障任务中高度依赖图像与文本等跨模态信息的高效关联。然而,主流跨模态检索模型虽然在通用数据集上表现优异,但对细粒度语义理解能力要求较高的领域表现不佳。为解决以上问题,基于可获取的民航领域数据集,提出一种细粒度语义增强的跨模态检索方法,构建涵盖数据处理、模型构建与训练的完整流程。基于多模态大模型对文本描述进行优化增强,构建涵盖丰富语义信息的跨模态检索数据集;基于主流跨模态检索框架设计模型,引入细粒度特征提取模块、类监督及关键语义信息掩码等策略,增强模型的细粒度语义特征表达能力。2个数据集上的实验结果验证了所提方法的有效性,可为低空经济场景下的跨模态检索需求提供可借鉴的技术路径。
Abstract:In the fields of low-altitude economy and civil aviation, security assurance tasks heavily rely on the efficient correlation of cross-modal information such as images and texts. However, while mainstream cross-modal retrieval models perform well on general datasets, they underperform in these areas, which require high levels of fine-grained semantic understanding. Based on existing civil aviation datasets, a cross-modal retrieval approach with fine-grained semantic augmentation is suggested as a solution to this problem, creating a whole pipeline that includes data processing, model development, and training. First, text descriptions are optimized and enhanced based on a large multimodal model to construct a cross-modal retrieval dataset containing rich semantic information. Second, a model is created using a popular cross-modal retrieval framework. To improve the model's ability to express fine-grained semantic features, techniques such class supervision, key semantic information masking, and a fine-grained feature extraction module are introduced. Experimental results on two datasets verify the effectiveness of the proposed method, providing a reference technical path for cross-modal retrieval in low-altitude economy scenarios.
-
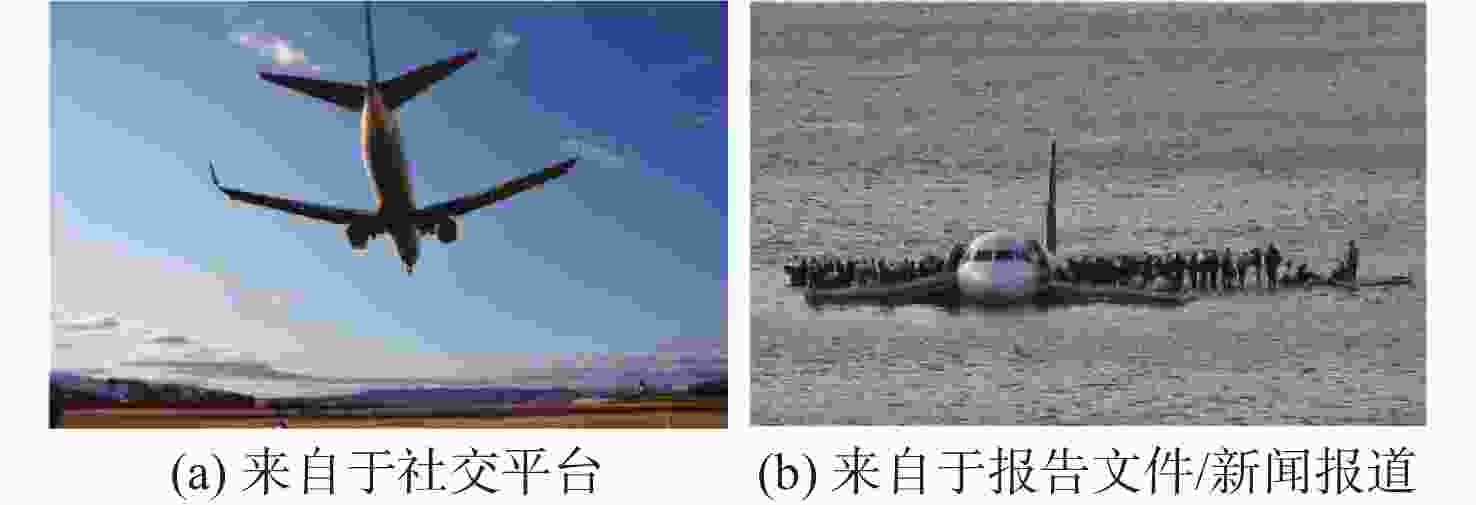
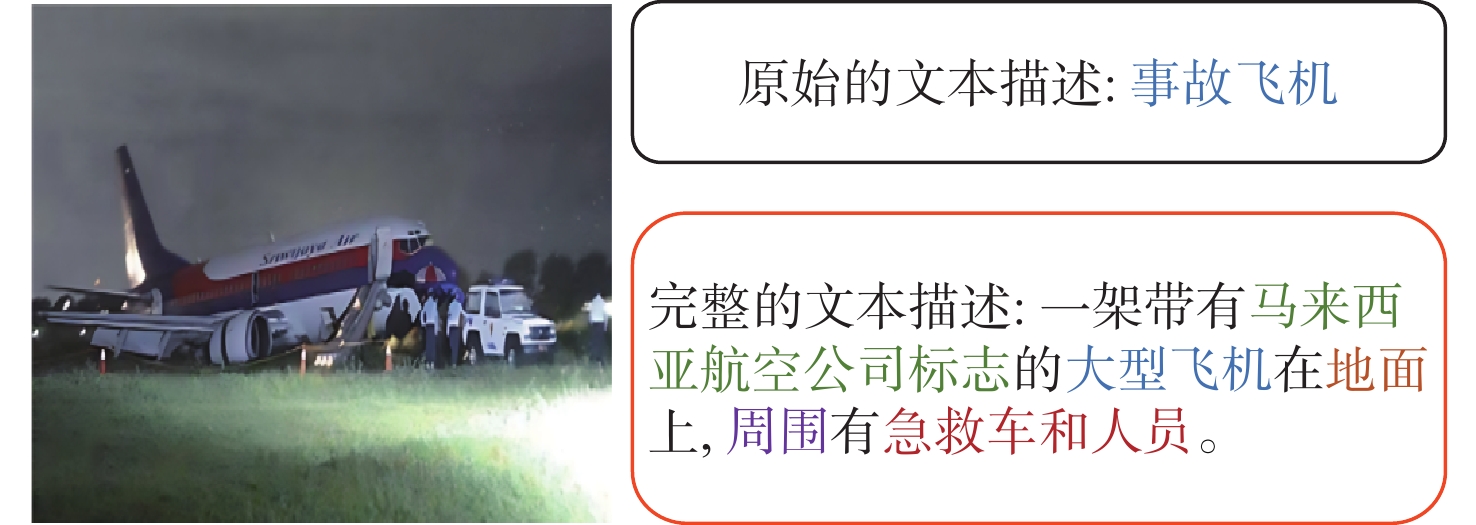
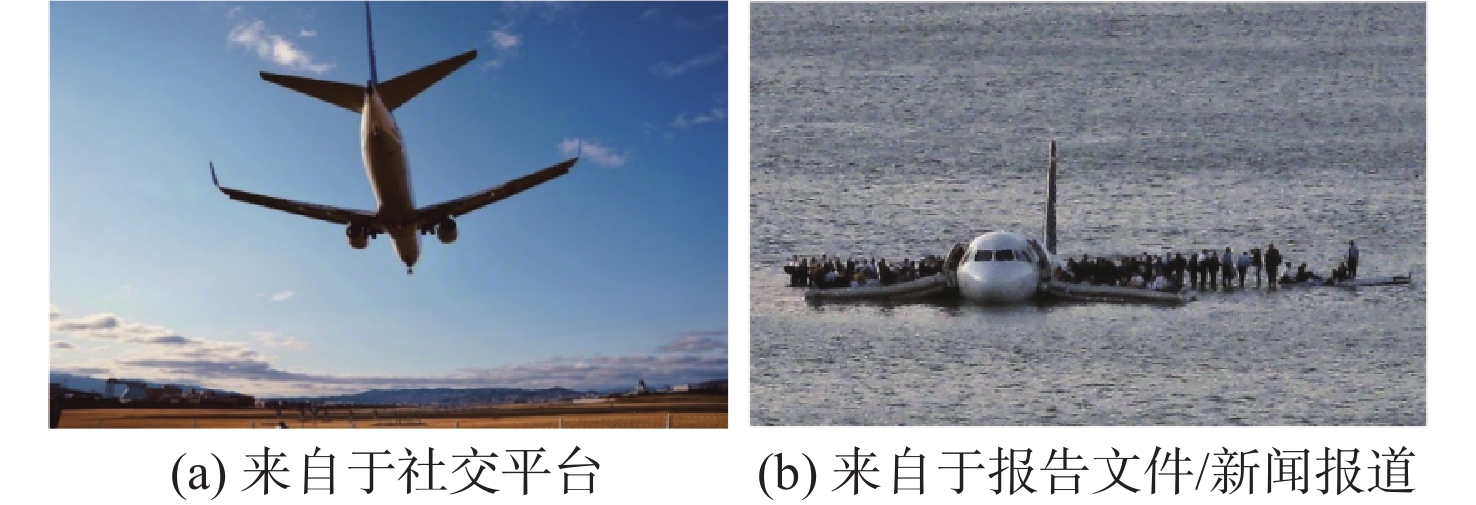
图 1 互联网中的民航领域图像-文本对数据示例
Figure 1. Examples of image-text pairs in civil aviation field on internet
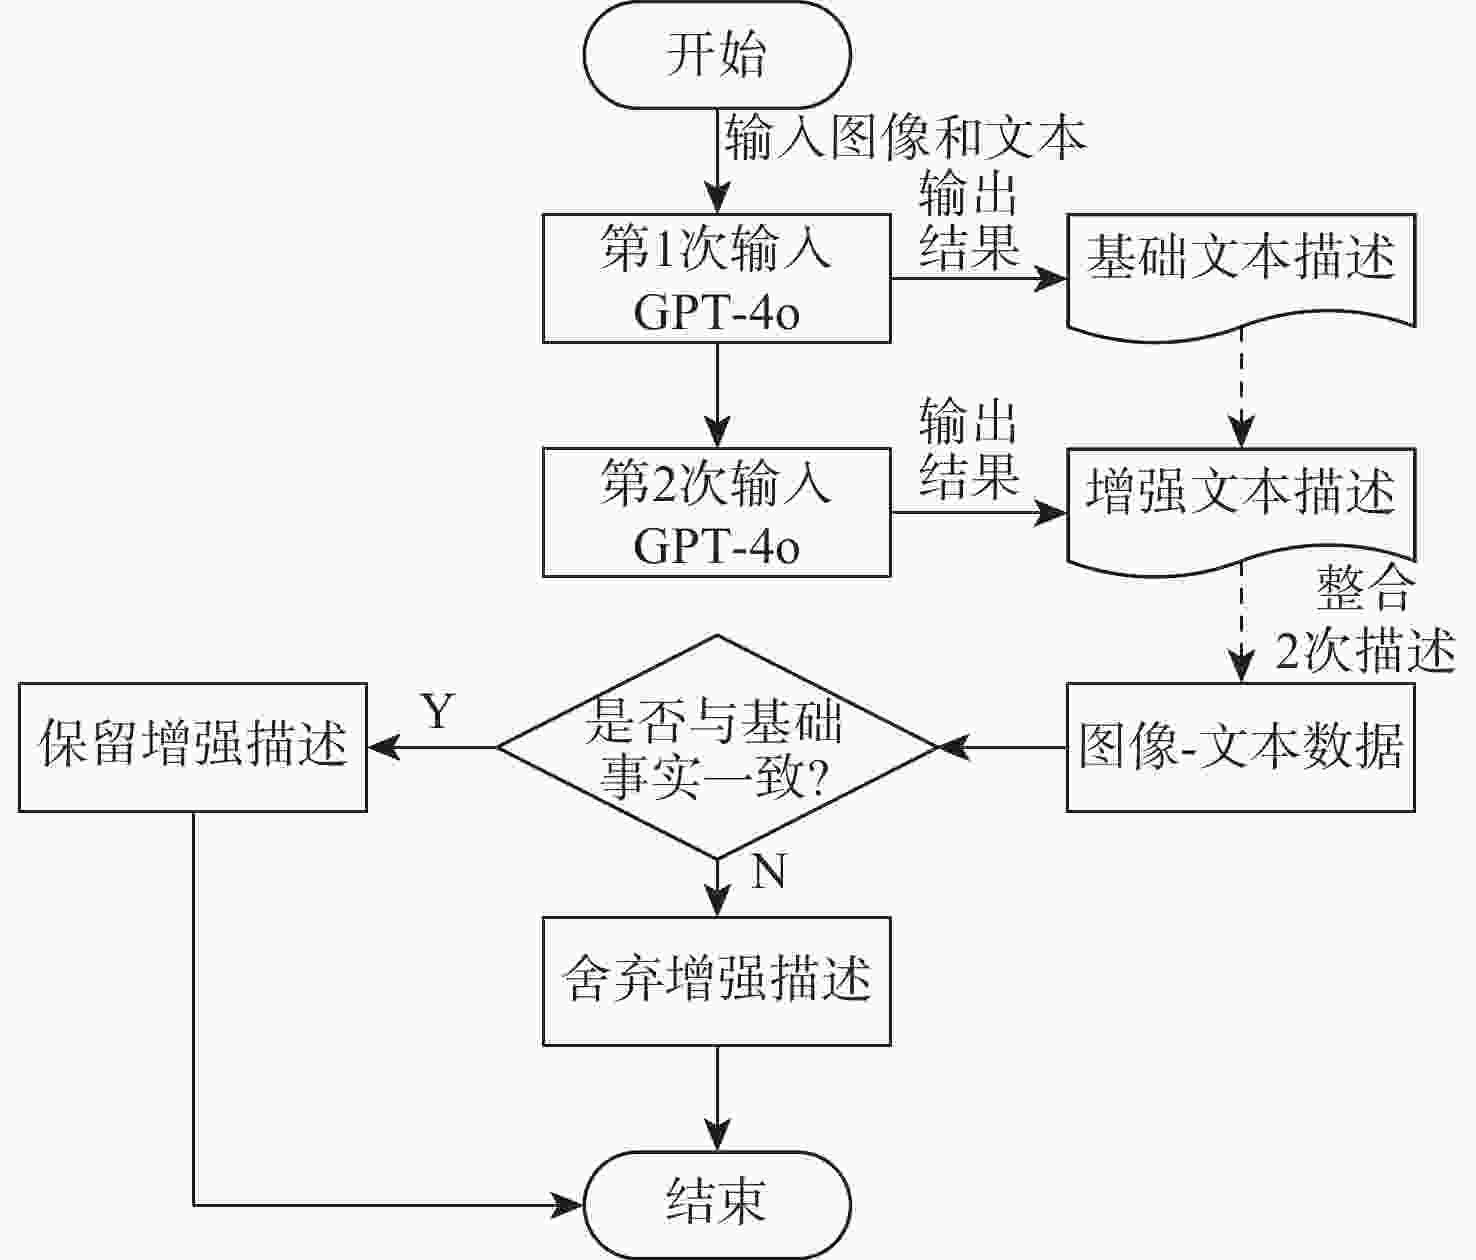
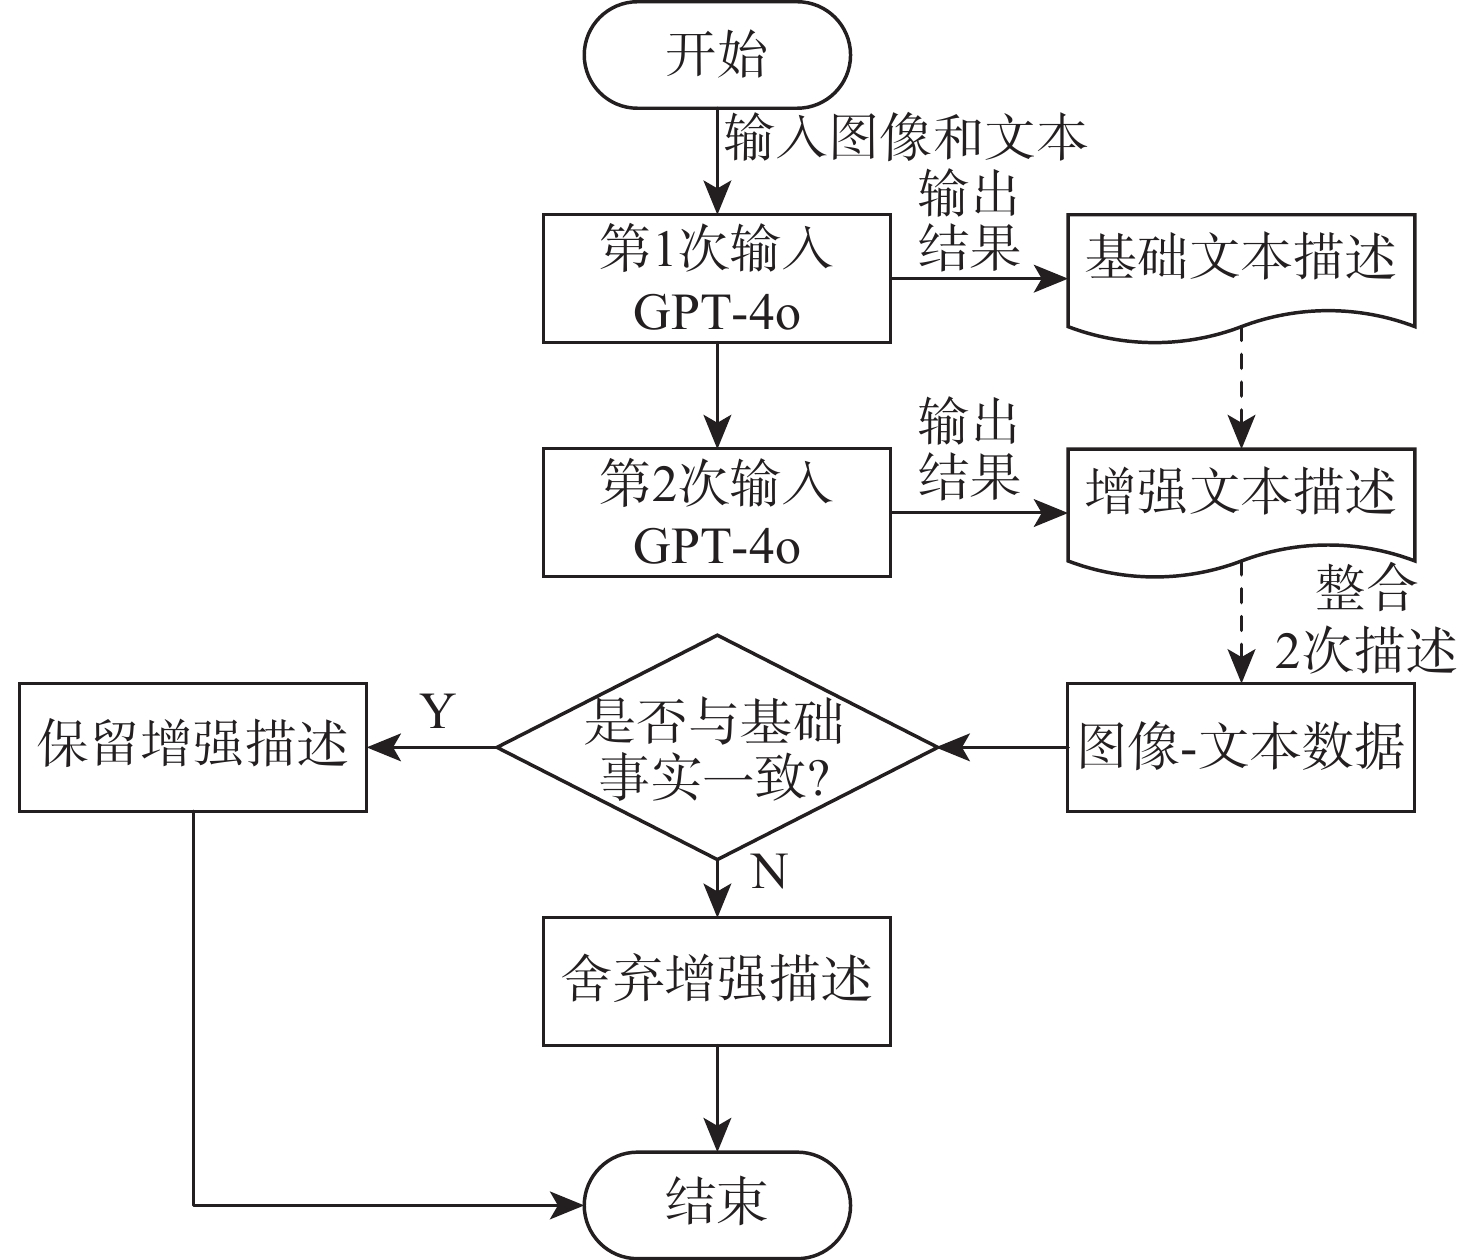
图 3 基于GPT-4o的文本描述生成和增强流程
Figure 3. Text description generation and enhancement process based on GPT-4o
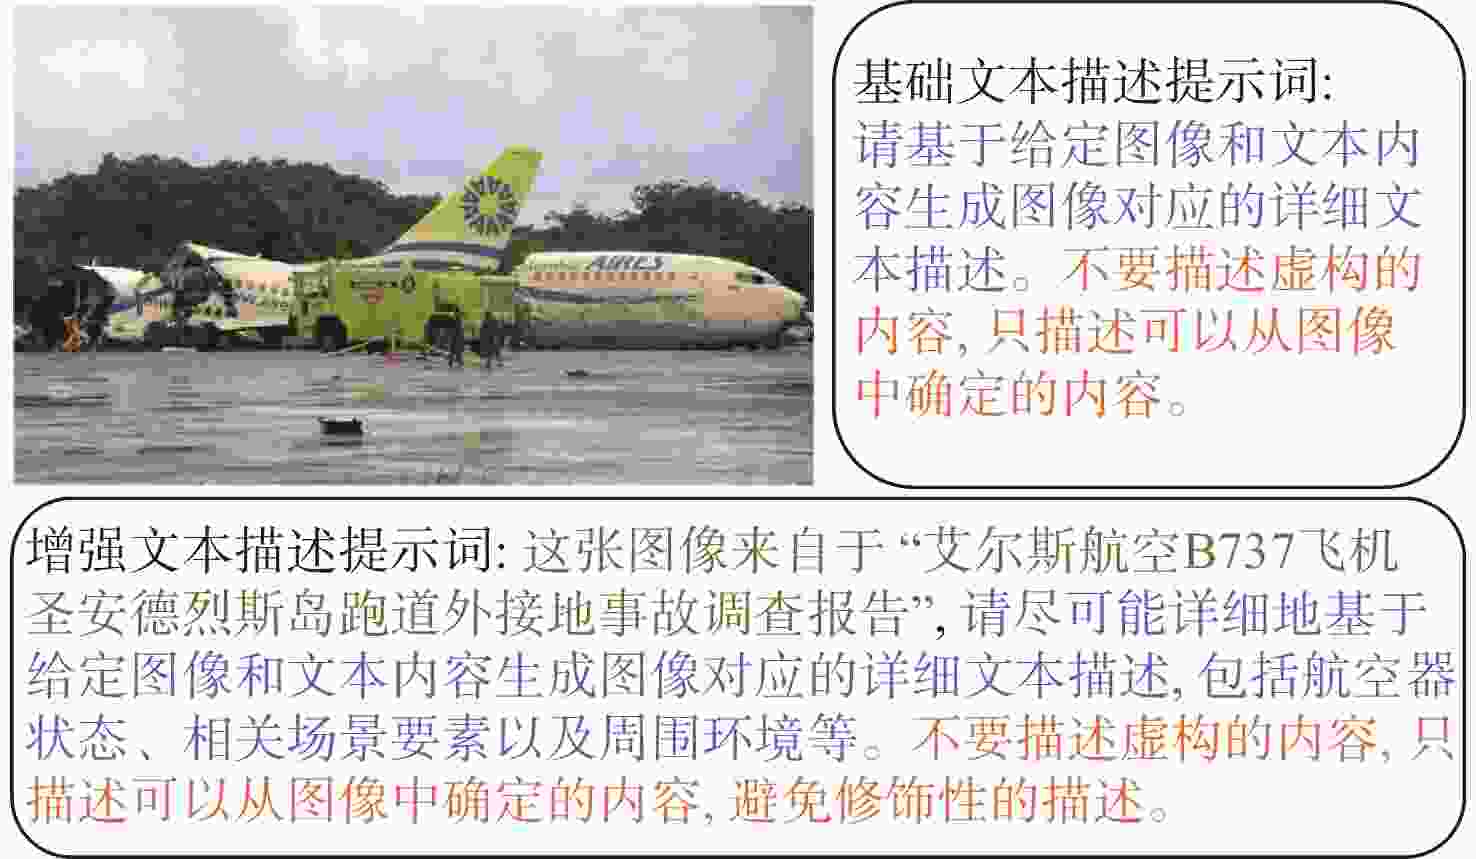
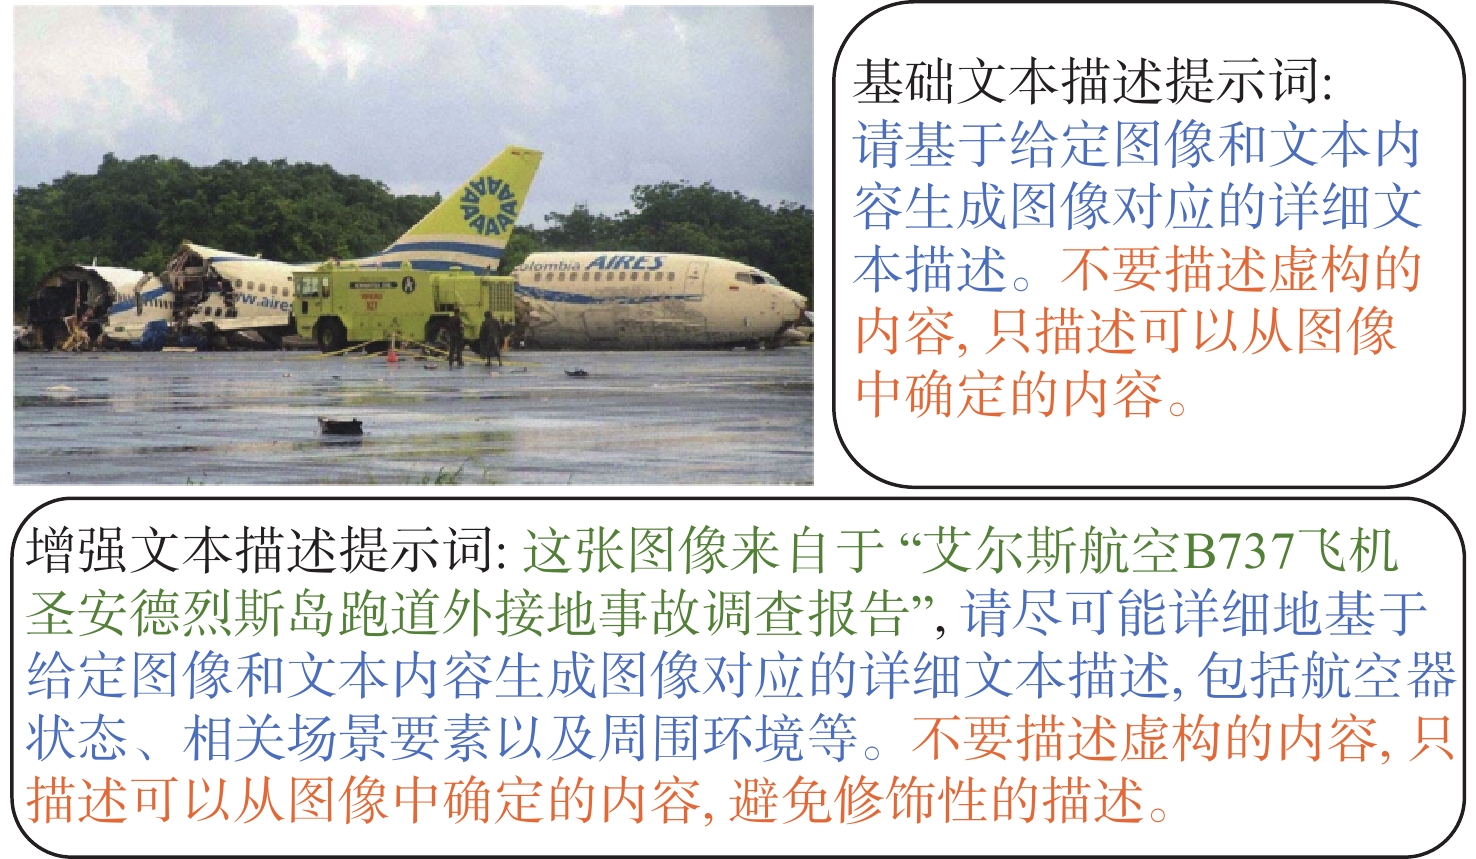
图 4 基于GPT-4o的文本描述生成与增强提示词示例
Figure 4. Example of caption generation and enhanced prompts based on GPT-4o
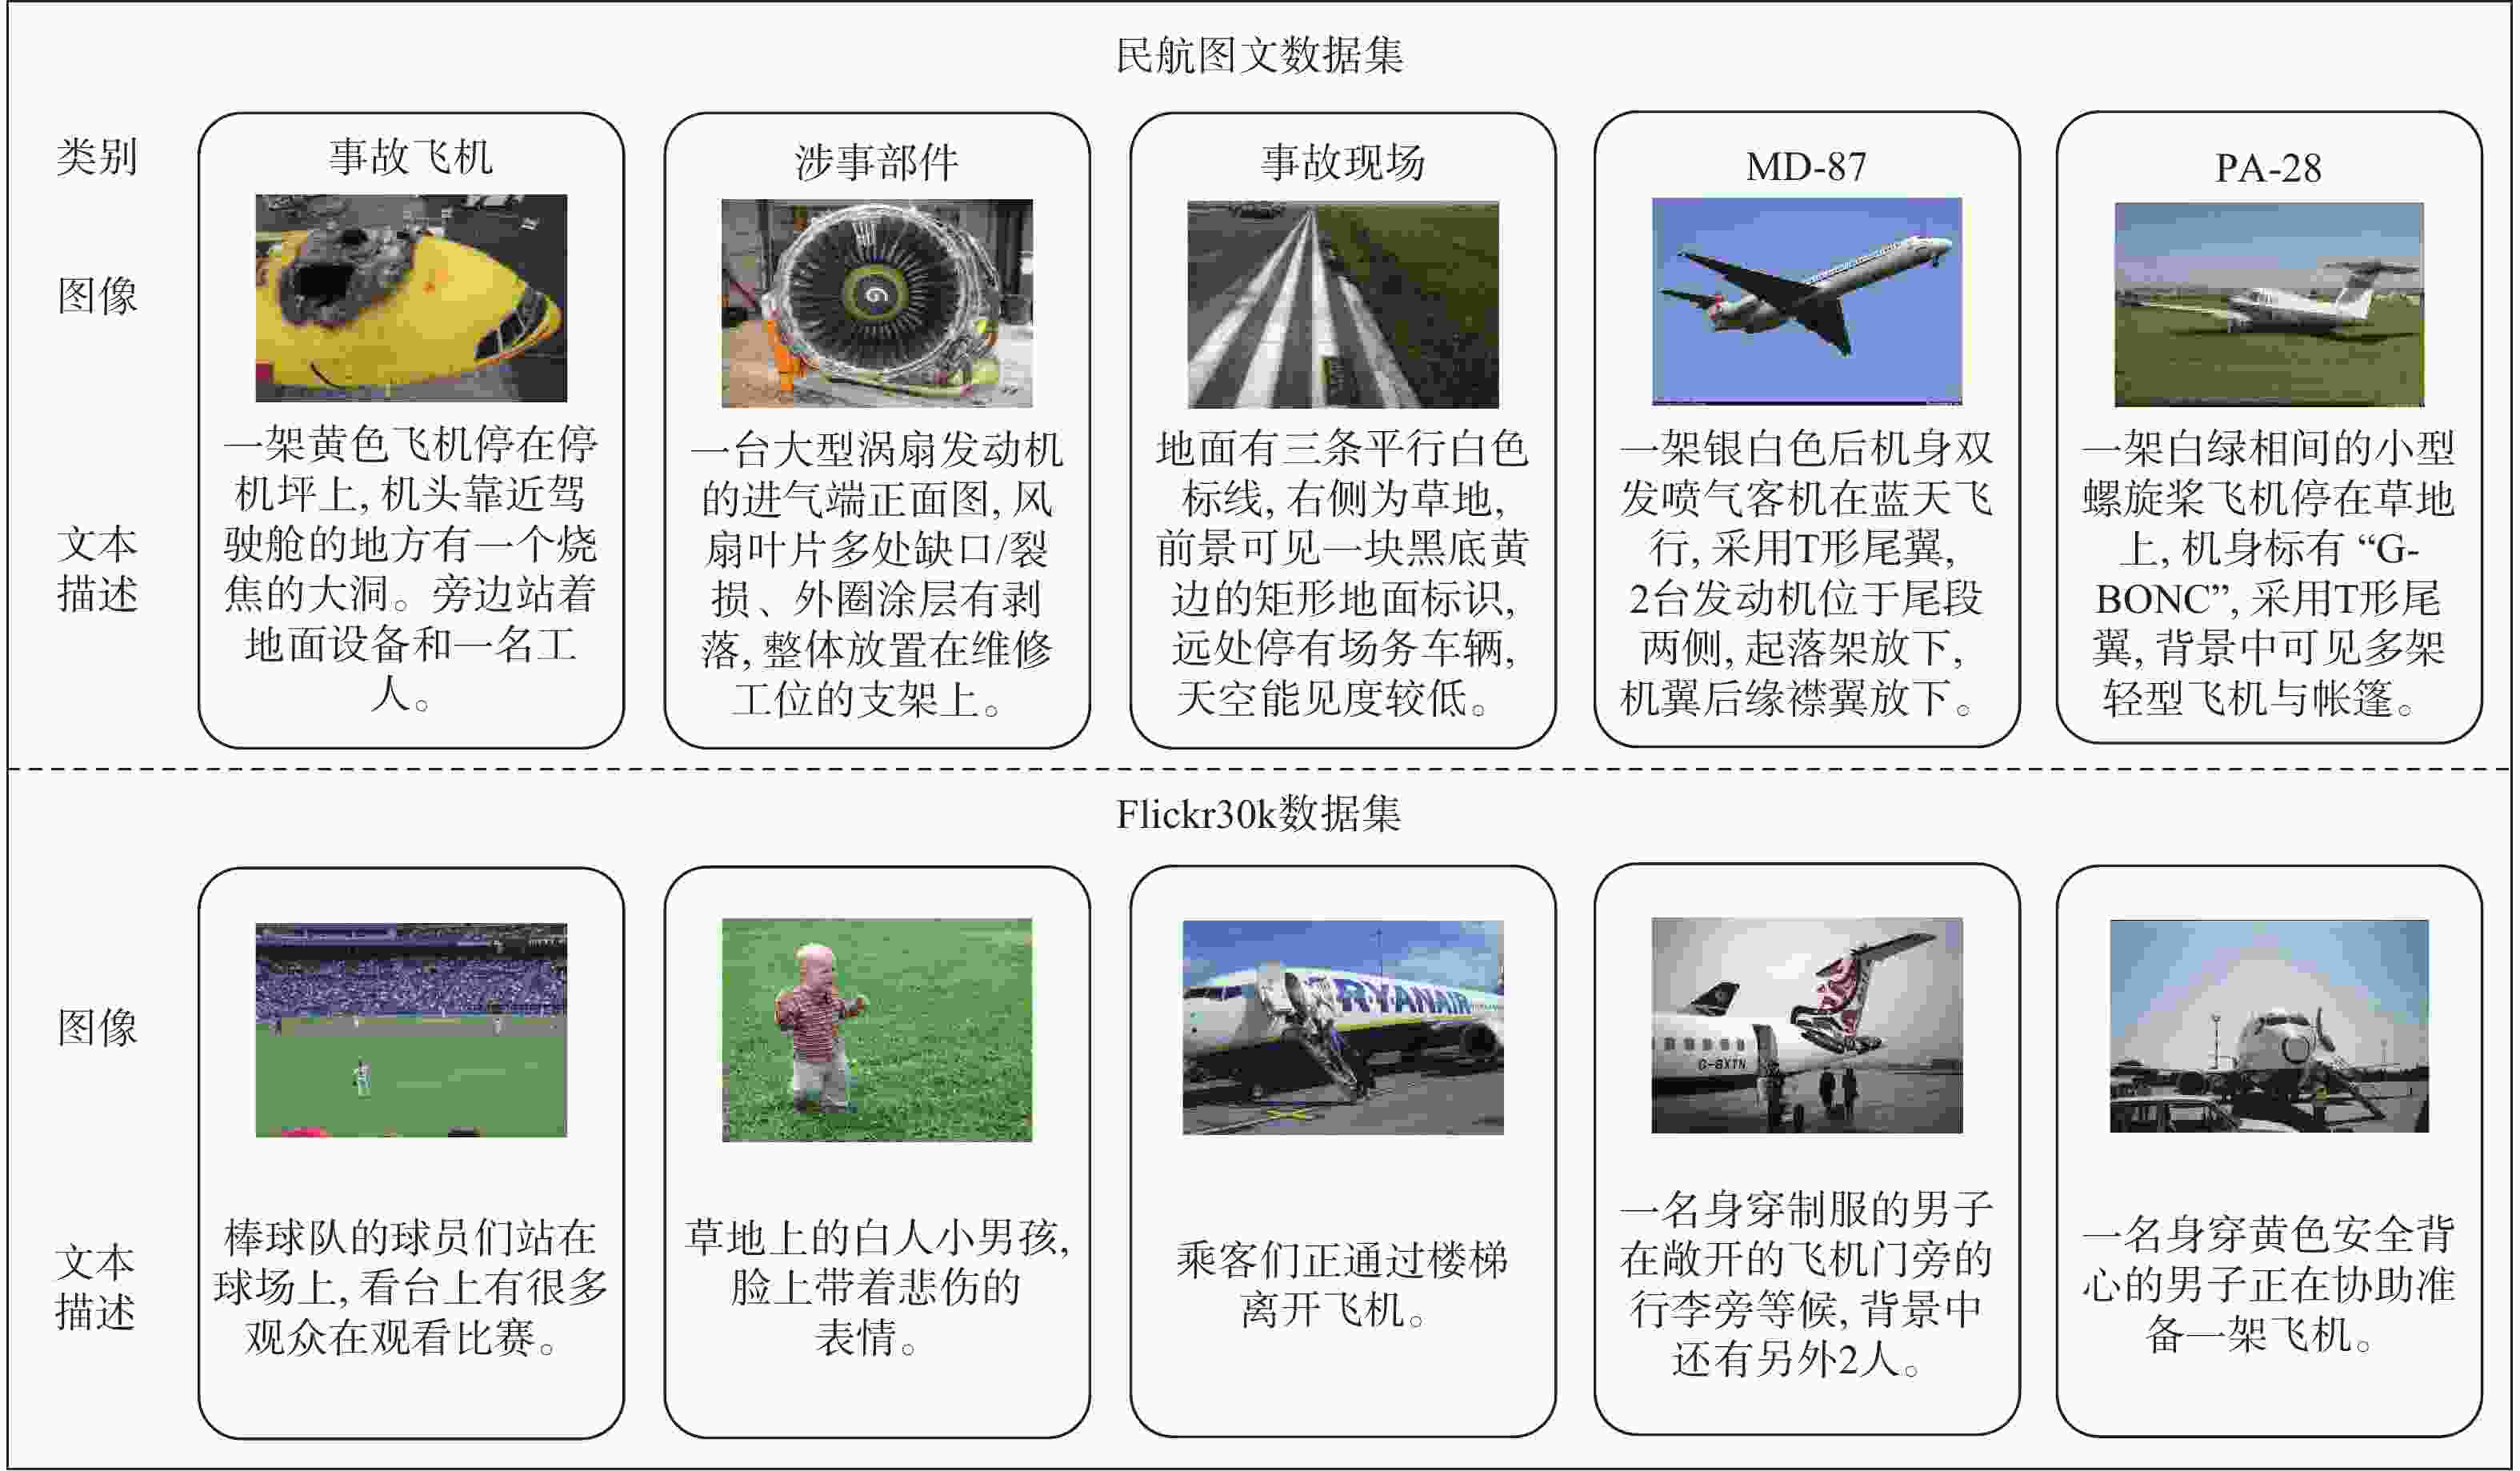
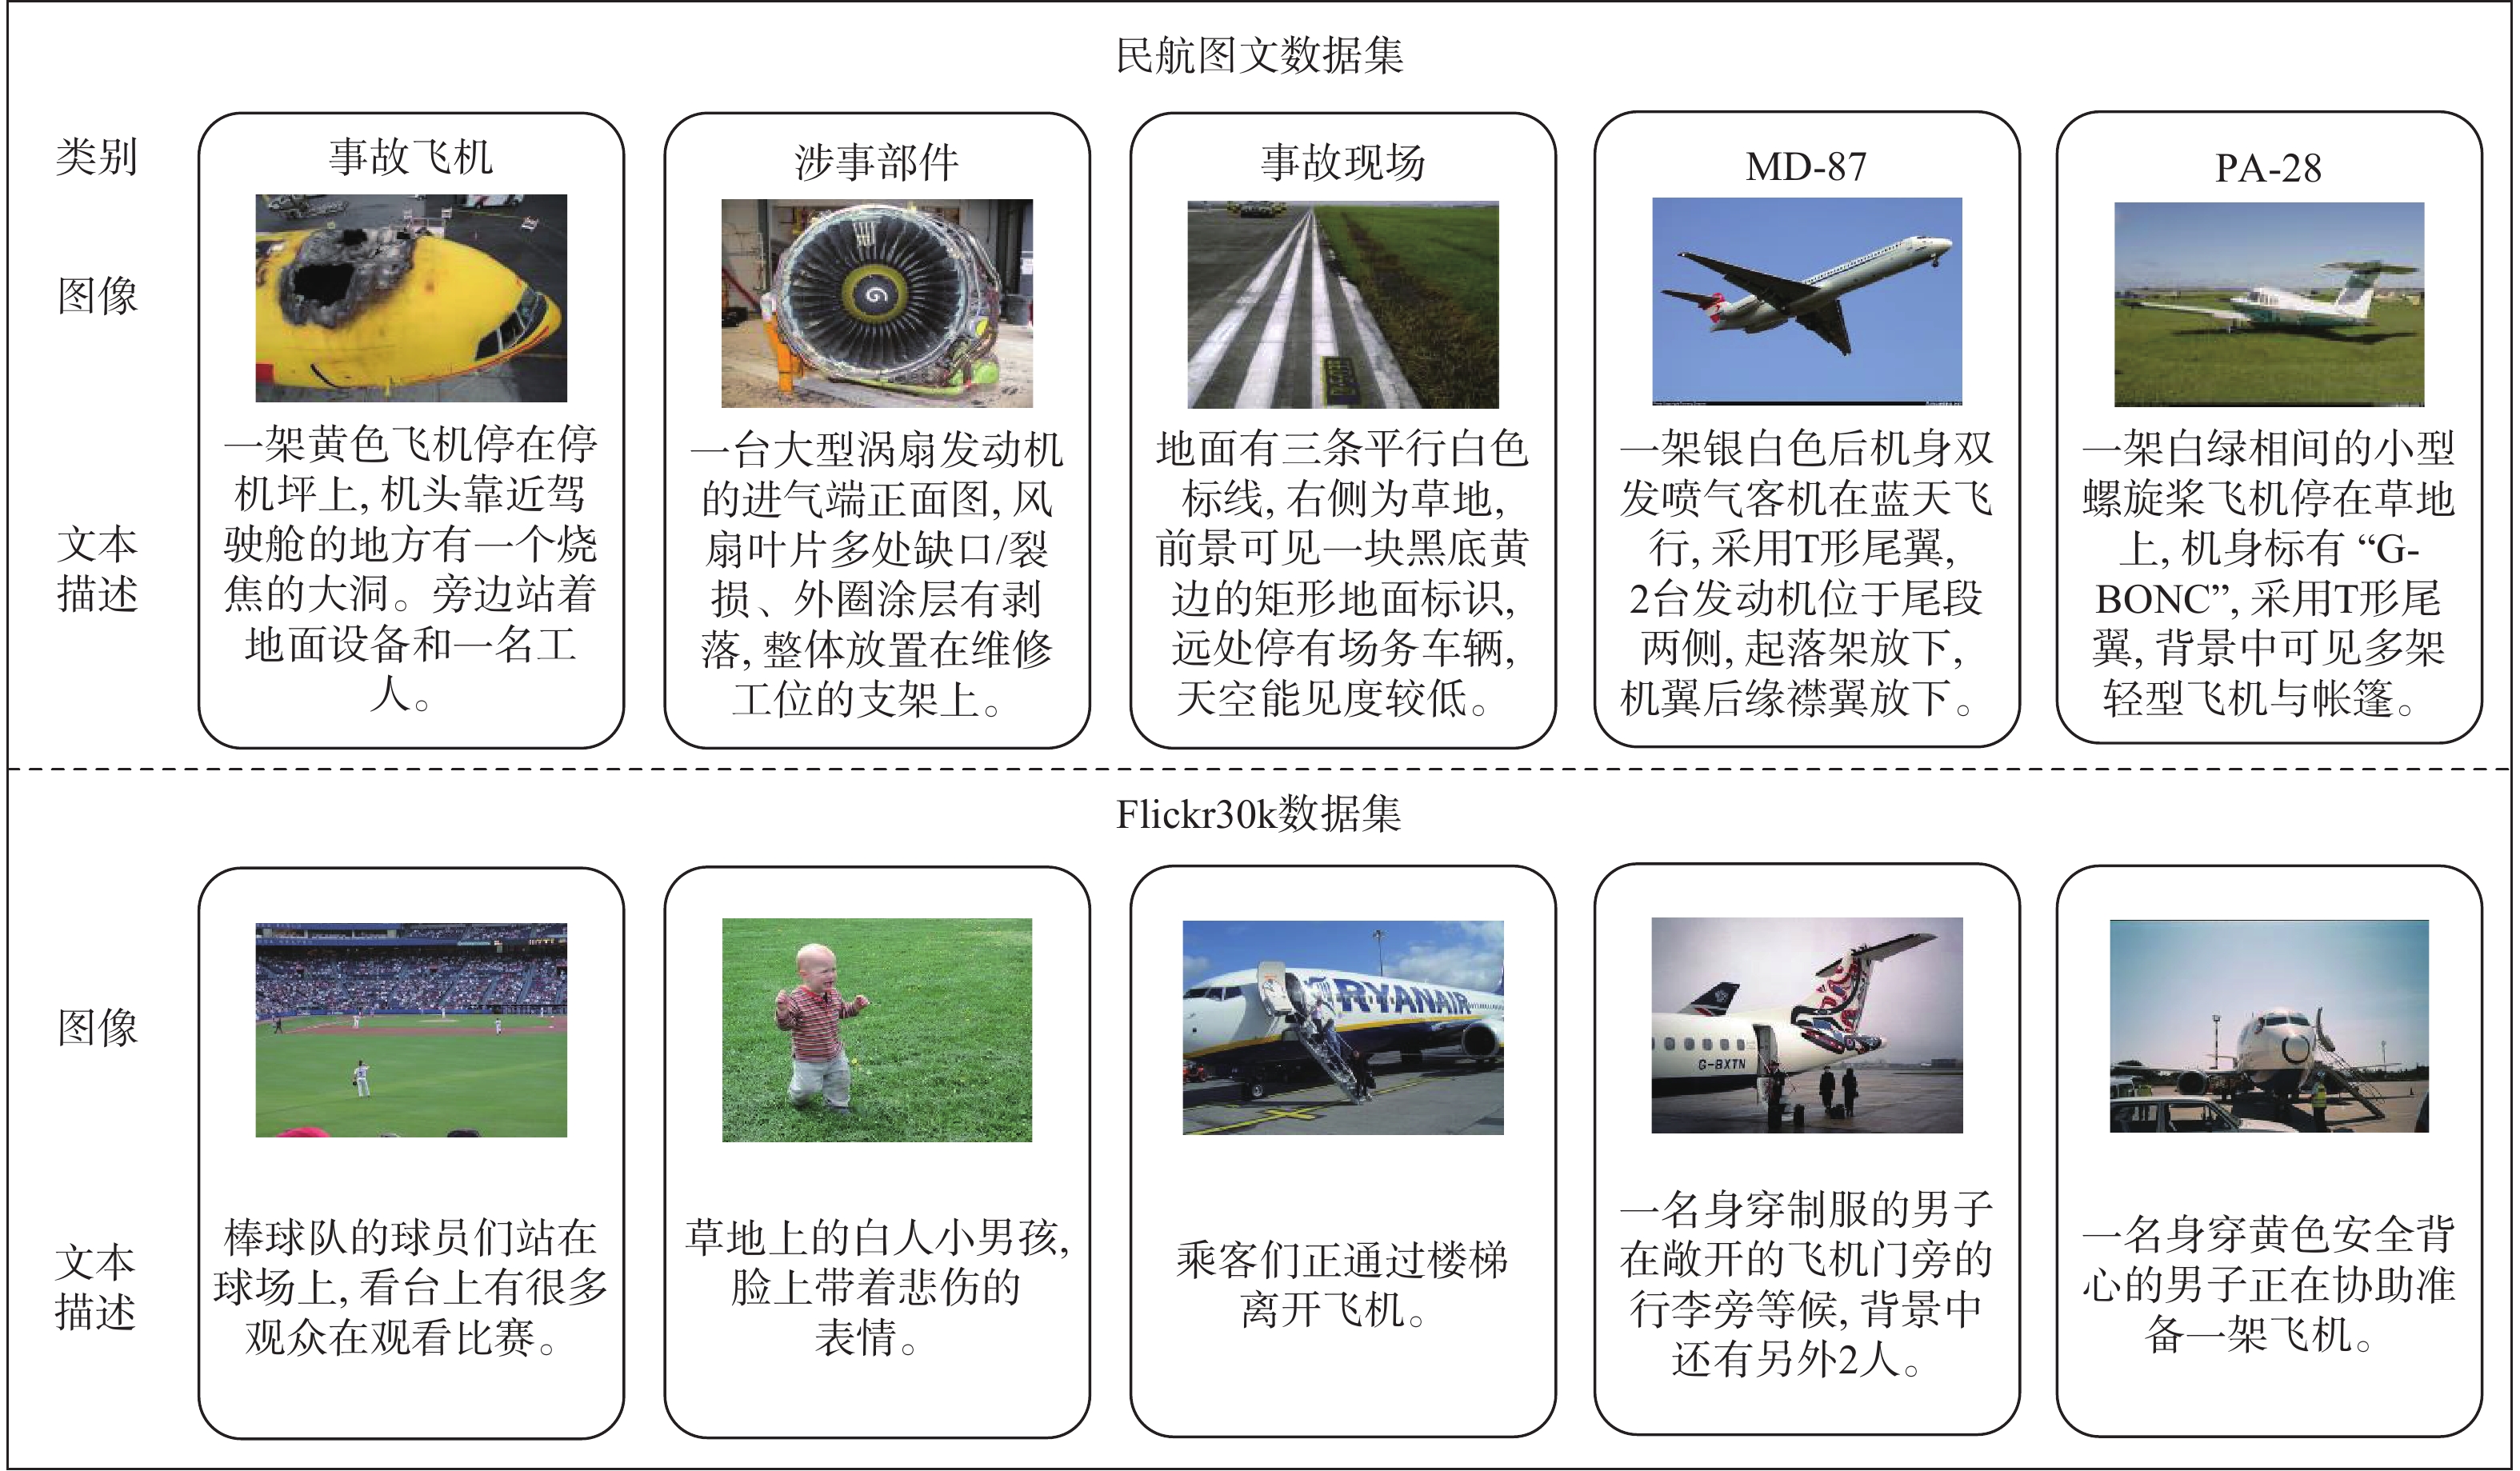
图 5 民航图文数据集和Flickr30k图文数据集示例
Figure 5. Examples of civil aviation image-text dataset and Flickr30k image-text dataset
表 1 民航领域数据集存在的问题
Table 1. Summary of problems with civil aviation datasets
数据集 图像 文本 类别 Accidents 存在非实物图像 粗粒度 无 FGVC Aircraft[28] 图像内容高度相似 无 有  下载: 导出CSV
表 2 语义闭包部分示例
Table 2. Some examples of semantic closure
语义闭包 部分示例 事故飞机 民机,货机,飞机,客机,事故飞机,涉事飞机 涉事部件 发动机,高压压气机,风挡玻璃,冷却圈,氧气软管 事故现场 机场图,事故现场,坠机现场着陆轨迹,接地痕迹 飞行轨迹 飞行轨迹,进近轨迹,飞行剖面,进近图,着陆过程 飞行环境 卫星云图,GOES雷达图,跑道布局图,红外卫星云图
下载: 导出CSV
表 3 不同模型在不同数据集上的实验结果
Table 3. Experimental results of different model on different datasets
% 数据集 模型 R@1 R@5 R@10 mR 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 Accidents CLIP[7] 12.99 15.59 25.68 28.64 34.44 38.49 25.97 ALBEF[8] 16.73 18.37 36.56 40.24 47.13 55.65 35.78 FLIP[9] 17.52 18.67 37.46 41.51 48.34 56.74 36.71 BLIP[20] 18.43 19.21 38.37 42.36 47.73 57.82 37.32 本文模型 20.54 21.39 39.88 43.81 48.34 58.33 38.72 FGVC Aircraft[28] CLIP[7] 4.92 4.22 10.74 14.55 19.56 25.75 13.29 ALBEF[8] 6.15 6.11 18.33 24.84 32.16 37.80 20.90 FLIP[9] 7.41 6.83 19.62 25.62 33.39 38.97 21.97 BLIP[20] 8.56 7.61 20.79 27.30 33.75 39.42 22.91 本文模型 10.62 9.56 22.92 28.59 34.62 40.35 24.44
下载: 导出CSV
表 4 基于GPT-4o的文本描述优化策略的消融实验结果(Accidents数据集)
Table 4. Ablation experiment results of text description optimization strategy based on GPT-4o (Accidents dataset)
% 文本描述 R@1 R@5 R@10 mR 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 原始标题 11.48 13.53 31.11 33.72 38.97 44.253 28.84 基础文本描述 17.22 18.21 37.16 41.63 47.43 55.650 36.22 增强文本描述 20.54 21.39 39.88 43.81 48.34 58.330 38.72
下载: 导出CSV
表 5 基于GPT-4o的文本描述优化策略的消融实验结果(FGVC Aircraft数据集)
Table 5. Ablation experiment results of text description optimization strategy based on GPT-4o (FGVC Aircraft dataset)
% 文本描述 R@1 R@5 R@10 mR 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 基础文本描述 7.32 7.01 19.23 25.83 32.55 37.11 21.51 增强文本描述 10.62 9.56 22.92 28.59 34.62 40.35 24.44
下载: 导出CSV
表 6 本文模型各模块的消融实验结果
Table 6. Ablation experiment results of the proposed model modules
% 数据集 模块 R@1 R@5 R@10 mR 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 以图像检索文本 以文本检索图像 Accidents 基础跨模态检索 15.71 16.61 34.74 38.37 44.11 53.78 33.89 细粒度特征提取模块 18.13 18.43 37.46 41.33 46.22 56.62 36.37 类监督策略 19.64 20.12 38.07 42.72 48.64 57.22 37.74 关键语义信息掩码策略 20.54 21.39 39.88 43.81 48.34 58.33 38.72 FGVC Aircraft[28] 基础跨模态检索 5.40 5.16 16.56 22.53 30.42 36.27 19.39 细粒度特征提取模块 7.35 6.92 19.35 25.27 32.79 38.59 21.71 类监督策略 9.10 7.85 21.51 27.34 33.67 39.57 23.17 关键语义信息掩码策略 10.62 9.56 22.92 28.59 34.62 40.35 24.44
下载: 导出CSV
-
[1] 郭辰阳, 敖万忠, 吕宜宏. 充分把握发展机遇, 加快推进低空经济高质量发展[J]. 财经界, 2022(25): 36-38.Guo C Y, Ao W Z, Lyu Y H. Fully grasp the development opportunities and accelerate the high-quality development of low-altitude economy[J]. Money China, 2022(25): 36-38(in Chinese). [2] 王淑鹤. 人工智能时代低空经济高质量发展的挑战和应对策略[J]. 产业创新研究, 2025(14): 39-41.Wang S H. Challenges and countermeasures of high-quality development of low-altitude economy in the era of artificial intelligence[J]. Industrial Innovation, 2025(14): 39-41(in Chinese). [3] 张若愚, 聂婕, 宋宁, 等. 基于布局化-语义联合表征遥感图文检索方法[J]. 北京航空航天大学学报, 2024, 50(2): 671-683.Zhang R Y, Nie J, Song N, et al. Remote sensing image-text retrieval based on layout semantic joint representation[J]. Journal of Beijing University of Aeronautics and Astronautics, 2024, 50(2): 671-683(in Chinese). [4] 王丹, 张峰, 张辉, 等. 基于信息互补与交叉注意力的跨模态检索方法[J]. 计算机应用研究, 2025, 42(7): 2032-2038.Wang D, Zhang F, Zhang H, et al. Information complementarity and cross-attention for cross-modal retrieval[J]. Application Research of Computers, 2025, 42(7): 2032-2038(in Chinese). [5] Vinyals O, Toshev A, Bengio S, et al. Show and tell: lessons learned from the 2015 MSCOCO image captioning challenge[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2017, 39(4): 652-663. [6] Plummer B A, Wang L W, Cervantes C M, et al. Flickr30k entities: collecting region-to-phrase correspondences for richer image-to-sentence models[J]. International Journal of Computer Vision, 2017, 123(1): 74-93. [7] Radford A, Kim J W, Hallacy C, et al. Learning transferable visual models from natural language supervision[C]//Proceedings of the International Conference on Machine Learning. Cambridge: JMLR, 2021: 8748-8763. [8] Li J, Selvaraju R, Gotmare A, et al. Align before fuse: vi-sion and language representation learning with momentum distillation[J]. Advances in Neural Information Processing Systems, 2021, 34: 9694-9705. [9] Li Y H, Fan H Q, Hu R H, et al. Scaling language-image pre-training via masking[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2023: 23390-23400. [10] 刘光才, 黄利萍, 李章萍, 等. 通用航空视角下我国低空经济的发展研判及欧美发展启示[J]. 中国物价, 2025(6): 42-48.Liu G C, Huang L P, Li Z P, et al. Analysis and prospects of China’s low-altitude economy development from the general aviation perspective and enlightenment from European and American development[J]. China Price Journal, 2025(6): 42-48(in Chinese). [11] Li D G, Dimitrova N, Li M K, et al. Multimedia content processing through cross-modal association[C]//Proceedings of the Eleventh ACM International Conference on Multimedia. New York: ACM, 2003: 604-611. [12] Zhang H, Liu Y, Ma Z G. Fusing inherent and external knowledge with nonlinear learning for cross-media retrieval[J]. Neurocomputing, 2013, 119: 10-16. [13] Frome A, Corrado G S, Shlens J, et al. Devise: a deep visual-semantic embedding model[C]//Proceedings of the 27th International Conference on Neural Information Processing Systems. New York: ACM, 2013: 2121-2129. [14] Mikolov T, Chen K, Corrado G, et al. Efficient estimation of word representations in vector space[EB/OL]. (2023-01-16)[2025-07-20]. https://arxiv.org/abs/1301.3781. [15] Lee K H, Chen X, Hua G, et al. Stacked cross attention for image-text matching[C]//Proceedings of the Computer Vision-ECCV. Berlin: Springer, 2018: 212-228. [16] Wehrmann J, Kolling C, C Barros R. Adaptive cross-modal embeddings for image-text alignment[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2020, 34(7): 12313-12320. [17] Qu L G, Liu M, Cao D, et al. Context-aware multi-view summarization network for image-text matching[C]//Proceedings of the 28th ACM International Conference on Multimedia. New York: ACM, 2020: 1047-1055. [18] Chen Y C, Li L J, Yu L C, et al. UNITER: universal image-text representation learning[C]//Proceedings of the Computer Vision-ECCV. Berlin: Springer, 2020: 104-120. [19] Li X J, Yin X, Li C Y, et al. Oscar: object-semantics aligned pre-training for vision-language tasks[C]//Proceedings of the Computer Vision-ECCV. Berlin: Springer, 2020: 121-137. [20] Li J N, Li D X, Xiong C M, et al. BLIP: bootstrapping language-image pre-training for unified vision-language understanding and generation[C]//Proceedings of the International Conference on Machine Learning. Cambridge: JMLR, 2022: 12888-12900. [21] Yu J H, Wang Z R, Vasudevan V, et al. CoCa: contrastive captioners are image-text foundation models[EB/OL]. (2022-06-14)[2025-07-30]. https://arxiv.org/abs/2205.01917. [22] Xiao R, Kim S, Georgescu M I, et al. FLAIR: VLM with fine-grained language-informed image representations[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2025: 24884-24894. [23] Tschannen M, Gritsenko A, Wang X, et al. SigLIP 2: multilingual vision-language encoders with improved semantic understanding, localization, and dense features[EB/OL]. (2025-02-20) [2025-08-01]. https://arxiv.org/abs/2502.14786. [24] Csizmadia D, Codreanu A, Sim V, et al. Distill CLIP (DCLIP): enhancing image-text retrieval via cross-modal transformer distillation[EB/OL]. (2025-06-16) [2025-08-01]. https://arxiv.org/abs/2505.21549. [25] Zhan G Q, Liu Y P, Han K, et al. ELIP: enhanced visual-language foundation models for image retrieval[EB/OL]. (2025-05-27) [2025-08-01]. https://arxiv.org/abs/2502.15682. [26] Beaumont R, Cherti M, Coombes T, et al. LAION-5B: an open large-scale dataset for training next generation image-text models[C]//Proceedings of the Advances in Neural Information Processing Systems 35. New York: ACM, 2022: 25278-25294. [27] 中国民航大学. 世界民航事故调查跟踪系列报告: 2010-2021[R]. 天津: 中国民航大学, 2010-2021.Civil Aviation University of China. World civil aviation accident investigation tracking report series: 2010-2021[R]. Tianjin: Civil Aviation University of China, 2010-2021(in Chinese). [28] Maji S, Rahtu E, Kannala J, et al. Fine-grained visual classification of aircraft[EB/OL]. (2013-06-21) [2025-08-01]. https://arxiv.org/abs/1306.5151. [29] Openai, Achiam J, Adler S, et al. GPT-4 technical report[EB/OL]. (2024-03-04)[2025-08-01]. https://arxiv.org/abs/2303.08774. [30] Fu S H, Yang Q Z, Mo Q J, et al. LLMDet: learning strong open-vocabulary object detectors under the supervision of large language models[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2025: 14987-14997. [31] Zheng L M, Chiang W L, Sheng Y, et al. Judging LLM-as-a-judge with MT-bench and chatbot arena[C]//Proceedings of the 37th International Conference on Neural Information Processing Systems. New York: ACM, 2023: 46595-46623. [32] Reimers N, Gurevych I. Sentence-BERT: sentence embeddings using Siamese BERT-networks[EB/OL]. (2019-08-27) [2025-08-01]. https://arxiv.org/abs/1908.10084. [33] He K M, Zhang X Y, Ren S Q, et al. Deep residual learning for image recognition[C]//Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2016: 770-778. [34] Hu J, Shen L, Sun G. Squeeze-and-excitation networks[C]//Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. Piscataway: IEEE Press, 2018: 7132-7141. [35] Dosovitskiy A, Beyer L, Kolesnikov A, et al. An image is worth 16x16 words: transformers for image recognition at scale[EB/OL]. (2021-06-03)[2025-08-01]. https://arxiv.org/abs/2010.11929. [36] Devlin J, Chang M W, Lee K, et al. BERT: pre-training of deep bidirectional transformers for language understanding[C]//Proceedings of the Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. Kerrville: Association for Computational Linguistics 2019: 4171-4186. [37] 张振兴, 王亚雄. 图文跨模态检索研究综述[J]. 北京交通大学学报, 2024, 48(2): 23-36.Zhang Z X, Wang Y X. A survey on image-text cross-modal retrieval[J]. Journal of Beijing Jiaotong University, 2024, 48(2): 23-36(in Chinese). -

 下载:

 点击查看大图
计量
- 文章访问数: 239
- HTML全文浏览量: 108
- PDF下载量: 21
- 被引次数: 0
